Quick Summary
Choosing the right LLM in healthcare is not just about benchmark scores anymore. This blog post compares the best healthcare LLMs using practical benchmarks, BAA support, licensing, and real-world use. You’ll also learn how to choose the right models for your needs, explore the top models on the market, understand the latest FDA guidance, and see how our team evaluates AI models before we work with clinical data.
Table of Contents
Introduction
A few years ago, MedQA scores were one of the main ways to compare LLMs in healthcare. Today, they are only one part of the decision.
Healthcare teams also need to know whether a model supports HIPAA requirements, offers a Business Associate Agreement (BAA), fits their licensing needs, performs well on real clinical tasks, and is trusted in production.
These factors have a much bigger impact on whether an LLM in healthcare can be safely used in hospitals, clinics, or healthcare applications than a leaderboard score alone.
This guide brings those factors together in one place. It compares the leading LLMs in healthcare using physician-reviewed benchmarks, security and compliance support, licensing, and real-world adoption to help you choose the right model for your use case.
What Are Large Language Models in Healthcare?
A large language model in healthcare is an AI model trained to understand and work with medical information. It can summarize clinical notes, answer patient questions, find information in electronic health records (EHRs), help with medical coding, and handle routine administrative tasks.
When used with the right security and compliance steps in place, deploying an LLM in healthcare can save time, cut down manual work, and improve patient care.
How We Scored These Healthcare LLMs: Benchmarks That Aren't MedQA
MedQA measures how well AI models answer multiple-choice medical questions. It has been the standard benchmark for evaluating an LLM in healthcare for years, but today’s top models score so closely that it no longer shows clear differences. That’s why we used additional benchmarks and evaluation factors to rank each model.
Why We Didn’t Rely Only on MedQA?
MedQA is based on real medical licensing exam questions, so it was once a good way to measure medical knowledge. Today, most leading healthcare LLMs score within a point or two of each other. It also only measures multiple-choice answers. It doesn’t test clinical reasoning, patient conversations, or healthcare tasks like medical coding and prior authorization.
Benchmarks We Used to Rank Each LLM in Healthcare
We compared models using multiple healthcare benchmarks instead of relying on just one.
- HealthBench Professional: Measures clinical reasoning using physician-written scoring rubrics. We gave this benchmark the highest weight because it better reflects real clinical work.
- HealthBench Hard: Focuses on difficult clinical questions that challenge even the best models.
- HealthAdminBench: Evaluates administrative tasks such as medical coding, claims summarization, and prior authorization.
How We Ranked the Models
Benchmark scores were only one part of our evaluation of each LLM in healthcare. We also considered:
- Performance across healthcare benchmarks
- HIPAA and BAA support or self-hosting options
- Commercial and clinical licensing
- Real-world healthcare use
- Deployment quality, including retrieval-augmented generation (RAG), safety guardrails, and human review
A model needed to perform well across all of these areas, not just one, to rank near the top.
Why Models Rank Differently
The same LLM in healthcare can rank differently across leaderboards because each benchmark measures different skills. Some focus on medical knowledge, while others evaluate clinical reasoning or administrative work. A higher rank only means the model performed better on that specific benchmark.
How Healthcare LLM Rankings Have Changed
- 2023-2024: MedQA became the main benchmark for comparing healthcare LLMs.
- Mid-2025: Most leading models achieved similar MedQA scores, making it harder to compare them.
- Late 2025: HealthBench introduced physician-reviewed evaluations that better reflected real clinical work.
- Early 2026: HealthBench Professional and HealthAdminBench added stricter clinical and administrative testing.
Today: Healthcare teams look beyond MedQA and compare models using multiple benchmarks, compliance, licensing, and real-world performance.
LLMs in Healthcare: Quick Comparison Table
Here’s a quick comparison among the best LLM for healthcare models to help you choose the right one.
| Model
|
Best For
|
BAA / Self-Hosted
|
Data Training/Retention
|
License
|
Context Window
|
Pricing (per 1M tokens, input/output)
|
| MedGemma 1.5 4B
|
Clinical imaging, radiology triage
|
Self-hosted
|
No vendor retention
|
Open (Health AI Developer Foundations)
|
128K tokens
|
Free weights, compute cost only
|
| Baichuan-M3
|
High-volume clinical Q&A
|
Self-hosted
|
No vendor retention
|
Open |
Not publicly confirmed
|
Free weights, compute cost only
|
| GPT-5.6 Sol
|
Complex diagnosis support, deep clinical reasoning
|
BAA via Azure OpenAI
|
Not used to train models on Azure enterprise terms
|
Proprietary, API-only
|
1M tokens
|
$5.00 / $30.00
|
| Claude Opus 4.8
|
Clinical documentation, long chart review
|
BAA via AWS Bedrock
|
Not used to train models by default on AWS Bedrock
|
Proprietary, API-only
|
1M tokens
|
$5.00 / $25.00
|
| GPT-OSS-120B
|
Self-hosted reasoning at lower cost
|
Self-hosted (BAA possible via hosted providers)
|
Self-hosted, or check your hosting provider's terms
|
Apache 2.0
|
128K tokens
|
Free self-hosted, roughly $0.05 / $0.20 hosted
|
| John Snow Labs Medical LLM Medium
|
On-prem clinical NLP, coding automation
|
Self-hosted / on-prem
|
Self-hosted/on-prem; no vendor retention
|
Commercial enterprise license
|
Not publicly specified
|
Custom enterprise licensing
|
| OpenBioLLM-70B
|
Biomedical research, literature Q&A
|
Self-hosted
|
No vendor retention
|
Llama 3 community license
|
Not publicly specified
|
Free weights, compute cost only
|
| Claude Sonnet 5
|
High-volume triage and summarization on a budget
|
BAA via Bedrock or Vertex AI
|
Not used to train models by default via Bedrock/Vertex AI
|
Proprietary, API-only
|
1M tokens
|
$3.00 / $15.00
|
| Gemini 3.1 Pro
|
Full patient chart review with long context
|
BAA via Google Cloud
|
Not used to train models on Google Cloud enterprise terms
|
Proprietary, API-only
|
1M tokens (1,048,576)
|
$2.00 / $12.00
|
| DeepSeek V4
|
Budget-constrained high-volume workloads
|
Self-hosted or hosted, no published BAA
|
No published retention policy
|
Open, permissive
|
128K tokens
|
$0.44 / $0.87 (Pro tier)
|
Note: Pricing shown reflects Anthropic’s standard post-introductory rate for Claude Sonnet 5 ($3.00 / $15.00 per million tokens). (Source)
Need to self-host for strict PHI compliance?
Choose MedGemma 1.5 4B, Baichuan-M3, GPT-OSS-120B, OpenBioLLM-70B, John Snow Labs Medical LLM Medium, or DeepSeek V4. These models can be deployed on your own infrastructure, helping organizations keep PHI within their environment.
Need a signed BAA and top clinical reasoning?
Choose GPT-5.6 Sol, Claude Opus 4.8, or Gemini 3.1 Pro. They support Business Associate Agreements (BAAs) through their cloud platforms and deliver strong clinical reasoning for enterprise healthcare applications.
Need a cost-effective model for high-volume tasks?
Choose Claude Sonnet 5, DeepSeek V4, or GPT-OSS-120B (hosted). They are well suited for high-volume workloads such as patient triage, medical coding, claims summarization, and clinical documentation.
Need a model designed specifically for clinical workflows?
Choose John Snow Labs Medical LLM Medium. It is built specifically for clinical NLP, medical coding, and compliance-focused on-premises healthcare deployments.
If you’re at the stage of scoping deployment rather than just comparing scores, LLM integration services can help you move from shortlist to production.
EHR Integration Reality
Benchmark scores only show how well a model performs on tests. They do not show whether the model can actually access patient records. In healthcare, how the model connects to an EHR is just as important as its accuracy.
- Claude Opus 4.8 / Claude Sonnet 5: No built-in EHR connection. To access Epic Systems, Oracle Health, or MEDITECH, you need an integration through Amazon Web Services Bedrock or custom middleware.
- GPT-5.6 Sol: Connects to Epic through Microsoft tools like Dragon Copilot and Azure Health Data Services. It does not have a direct OpenAI-to-EHR connection.
- Gemini 3.1 Pro: Connects to EHRs through Google Cloud Healthcare API and partner integrations. It does not include a built-in Epic or Oracle Health connection.
- MedGemma 1.5 4B, Baichuan-M3, GPT-OSS-120B, OpenBioLLM-70B, and DeepSeek V4: These are self-hosted models and do not include built-in EHR integration. You need custom middleware to connect them to Epic, Oracle Health, or MEDITECH.
- John Snow Labs Medical LLM Medium: Typically deployed alongside an organization’s existing EHR pipeline through vendor-supported connectors, rather than a plug-and-play App Orchard listing.
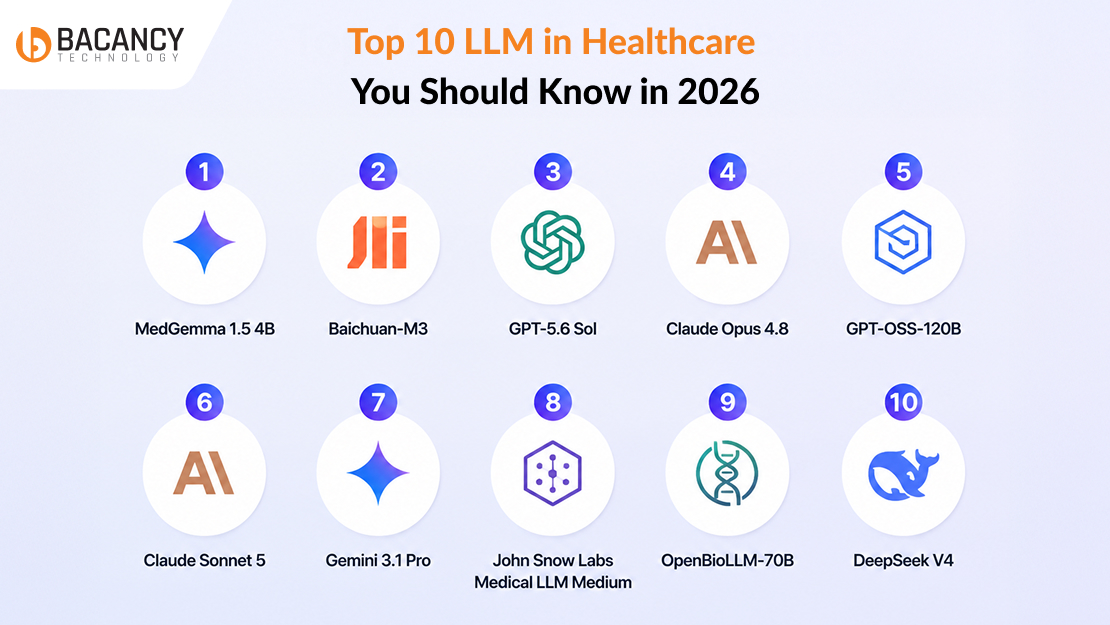
Top 10 LLM in Healthcare You Should Know in 2026
Here’s a detailed look at the top LLM in healthcare options, including their capabilities, strengths, deployment options, and best-fit healthcare applications.
Top 10 LLM in Healthcare You Should Know in 2026:
1. MedGemma 1.5 4B
2. Baichuan-M3
3. GPT-5.6 Sol
4. Claude Opus 4.8
5. GPT-OSS-120B
6. Claude Sonnet 5
7. Gemini 3.1 Pro
8. John Snow Labs Medical LLM Medium
9. OpenBioLLM-70B
10. DeepSeek V4
1. MedGemma 1.5 4B
MedGemma is Google’s open-weight LLM in healthcare built under its Health AI Developer Foundations program. Unlike general LLMs that are later fine-tuned for healthcare, MedGemma was built specifically for medical imaging and clinical text from the start.
With 4 billion parameters, MedGemma is small enough to run on a hospital’s own servers. This makes it a good choice for healthcare organizations that want to keep patient data inside their own systems instead of sending it to a cloud API.
What this means for your team:
- Runs on infrastructure you already control, so radiology and pathology images never leave your network.
- Handles image and text together in one pass, useful for triaging scans before a radiologist reviews them.
- Needs less computing power than large 70B+ models, helping reduce infrastructure costs.
2. Baichuan-M3
Baichuan-M3 is a medical-focused LLM developed by Baichuan AI, and it’s one of the strongest open-model performers on HealthBench, a benchmark that measures how well AI models handle real clinical tasks.
According to Baichuan’s own published benchmark results, the model surpassed GPT-5.2, OpenAI’s frontier model at the time of M3’s January 2026 release, on clinical inquiry and hallucination rate.
These results were published before GPT-5.6 Sol was released, so they are not a direct comparison with today’s latest models.
What this means for your team:
- No per-token API costs, making it a good choice for high-volume healthcare applications.
- You can run it on your own servers, so patient data stays inside your organization.
- Strong HealthBench performance means you get good clinical reasoning without relying on expensive cloud APIs.
3. GPT-5.6 Sol
GPT-5.6 Sol is OpenAI’s latest frontier LLM for healthcare. It is available through Azure OpenAI, so healthcare organizations get a Business Associate Agreement (BAA) through Microsoft instead of OpenAI.
It also has the highest HealthBench Professional score among the models in this comparison. This benchmark focuses on real clinical reasoning instead of medical trivia.
What this means for your team:
- Best for complex clinical decisions, not simple medical questions.
- Available through Azure OpenAI, making it easier to use in healthcare organizations that already use Microsoft services.
- The higher cost is worth it for low-volume, high-risk tasks like complex case reviews, where accuracy matters most.
4. Claude Opus 4.8
Claude Opus 4.8 is Anthropic’s flagship LLM for healthcare. It is available through AWS Bedrock, where healthcare organizations can get a Business Associate Agreement (BAA).
Its biggest strength is handling long patient records. It can review years of patient history and remember important details throughout the document, making it useful for full chart reviews and clinical documentation.
In practice, that’s a 1M-token context window across the API, AWS Bedrock, Google Cloud, and Microsoft Foundry, roughly 750,000 words in a single request.
What this means for your team:
- Great for discharge summaries, chart reviews, and long clinical notes.
- Available through AWS Bedrock, making it easy to use if your healthcare organization already runs on AWS.
- Can process long patient records in a single request, reducing costs and lowering the chance of missing important information.
5. GPT-OSS-120B
GPT-OSS-120B is OpenAI’s open source LLM for healthcare, released under the Apache 2.0 license. This license allows healthcare organizations to use, modify, and deploy the model in commercial applications.
It has the highest HealthBench Hard score among the open models in this comparison. This makes it one of the best choices for organizations that want strong clinical reasoning while running the model on their own infrastructure.
What this means for your team:
- The Apache 2.0 license lets you use and deploy the model in commercial healthcare applications without the restrictions found in some community licenses.
- You can run it on your own servers or use a hosted provider with a BAA, typically for around $0.05 / $0.20 per million input/output tokens, without managing the infrastructure yourself.
- Offers clinical reasoning close to frontier models at a much lower cost.
6. Claude Sonnet 5
Claude Sonnet 5 is Anthropic’s mid-tier LLM for healthcare. It is a more affordable option than Claude Opus 4.8, making it a good choice for teams with a smaller budget.
It costs much less per token, which can lead to significant savings for healthcare organizations running millions of AI requests each month.
What this means for your team:
- A good choice for patient message triage, clinical summarization, and claims processing at hospital scale.
- Uses the same BAA setup as Claude Opus 4.8, so you can switch between the two models without going through a new compliance process.
- Lower cost per token helps reduce costs for healthcare organizations handling millions of AI requests each month.
7. Gemini 3.1 Pro
Gemini 3.1 Pro is Google’s frontier LLM and one of the best long-context models for healthcare. It is available through Google Cloud, where healthcare organizations can get a Business Associate Agreement (BAA).
Its biggest strength is its large context window. It can process a complete EHR export, including years of clinical notes and lab results, in a single request instead of splitting the record into smaller parts. Google’s model card puts that ceiling at up to 1M tokens (1,048,576), with a 64K-token output limit.
What this means for your team:
- Best for full patient chart reviews, where splitting records into smaller sections could miss important clinical details.
- Available through Google Cloud, making it a good choice for healthcare organizations already using GCP.
- Costs less than GPT-5.6 Sol and Claude Opus 4.8, making it a more affordable option for long-context healthcare workloads.
8. John Snow Labs Medical LLM Medium
John Snow Labs Medical LLM Medium is different from most other healthcare LLMs. Instead of starting as a general-purpose model and later being adapted for healthcare, it was built specifically for clinical NLP and medical coding.
This makes it well suited for tasks such as converting clinical notes into ICD-10 and CPT codes, where general-purpose LLMs may not be accurate enough for production use.
What this means for your team:
- Built specifically for medical coding and clinical NLP, so it performs these tasks better than most general-purpose LLMs.
- Uses a commercial enterprise license, giving you vendor support instead of just an API key.
- Can be deployed on your own servers, helping healthcare organizations keep PHI inside their own environment while receiving vendor support.
9. OpenBioLLM-70B
OpenBioLLM-70B is a healthcare LLM built mainly for biomedical research, not for day-to-day clinical use. It is designed to search medical literature and answer research-related questions.
It is released under the Llama 3 Community License, so healthcare organizations should review the license terms before using it in commercial applications.
What this means for your team:
- Best for research teams working with medical literature, not for patient-facing applications or medical coding.
- Free to self-host, so research teams can deploy it on their own infrastructure without paying API fees.
- Review the license before commercial use, as the Llama 3 Community License has more restrictions than the Apache 2.0 license.
10. DeepSeek V4
DeepSeek V4 is one of the most affordable LLMs for healthcare in this comparison. It costs $0.44 per million input tokens and $0.87 per million output tokens on its Pro tier, while still delivering reasoning performance close to frontier models.
The main limitation is compliance. At the time of writing, no published Business Associate Agreement (BAA) is available for either the self-hosted or hosted version.
What this means for your team:
- The cheapest way to run high-volume workloads that don’t touch protected health information directly.
- Fits de-identified data pipelines, research analytics, or administrative tasks outside the PHI boundary.
- Not a fit yet for anything requiring a signed BAA, so keep it out of direct patient data workflows until that changes.
Not sure which healthcare LLM best fits your organization?
Opt for our healthcare IT services to build secure, compliant, and scalable AI solutions tailored to your needs.
Regulatory and Legal Considerations for Clinical LLMs
Before you deploy an LLM in healthcare, you need to know which rules actually apply to it. That depends on where it’s used, what it does, and whether it’s making clinical calls or just supporting them. Get this right, and you cut your legal risk while keeping patients safer.
FDA Guidance (U.S.)
The FDA’s January 2026 Clinical Decision Support (CDS) guidance makes it easier for some AI-powered clinical tools to remain outside medical device regulation. One important update is that a CDS tool can give one recommendation if it is the only clinically appropriate option and meets all of the FDA’s other requirements.
To remain outside FDA regulation, the tool should:
- Let clinicians independently review the recommendation.
- Clearly disclose supporting sources and reasoning.
- Avoid time-critical clinical decisions.
- Document model validation, intended use, training population, and known limitations.
LLMs used for documentation or chart summarization generally face lower regulatory risk than those supporting diagnosis or emergency care.
EU Compliance
Organizations serving European healthcare providers must address additional requirements beyond HIPAA and FDA guidance, including:
- GDPR rules for processing health data.
- The EU AI Act, which may classify many healthcare AI systems as high risk.
- Regional data residency and privacy obligations.
As a result, organizations operating in both the U.S. and Europe need separate compliance strategies for any LLM in healthcare they deploy.
Legal Liability
Following the rules doesn’t mean you’re off the hook legally. A 2026 lawsuit against OpenAI claims ChatGPT gave bad advice that delayed care for a user with a life-threatening condition, and the suit accuses the company of negligence. It’s a reminder that a disclaimer won’t save you if your AI is basically acting like a doctor.
To reduce risk, clinical LLMs should:
- Clearly define their intended use.
- Escalate high-risk symptoms to clinicians.
- Include safeguards beyond simple disclaimers.
Certification Inheritance
No LLM in this comparison has its own SOC 2 or HITRUST CSF certification. These certifications come from the cloud platform or infrastructure where the model is deployed.
- Claude Opus 4.8 and Claude Sonnet 5 can inherit certifications when deployed through AWS Bedrock or Google Cloud Vertex AI.
- GPT-5.6 Sol inherits certifications when deployed on Microsoft Azure.
- Gemini 3.1 Pro inherits certifications when deployed on Google Cloud.
- Self-hosted open-weight models do not inherit any certifications. Your own infrastructure must meet compliance requirements.
If your organization requires HITRUST or SOC 2, verify that your hosting environment is certified. The certification applies to the infrastructure, not the AI model itself.
How Bacancy Technology Evaluates Healthcare LLMs Before Deployment
At Bacancy Technology, we offer healthcare AI solutions to help organizations choose the right healthcare LLM. Every model is evaluated against the client’s use case, data, compliance requirements, and deployment environment before we make a recommendation.
1. Start with the Use Case
Every engagement starts with knowing what the model should be able to do. It might be decision support, coding, claim processing, patient communications, or clinical documentation, but each scenario has its own unique accuracy and workflow requirements that need to be defined before we can pick the correct model.
2. Test on Real Healthcare Data
The results from benchmark tests do not always show how well the program works in the real world. For that reason, we test our selected models through the use of de-identified medical data, which includes EHRs, doctors’ notes, intake forms, among others.
3. Recommend the Right Deployment Approach
How you deploy depends on your own security and compliance needs. Some clients want a self-hosted open-weight model so they keep tighter control over PHI. Others are satisfied with managed cloud services like Azure OpenAI, AWS Bedrock, or Vertex AI, as long as the right HIPAA safeguards are in place. We just recommend whatever fits your setup and risk tolerance best.
4. Build Safety and Governance into the Solution
The development of a fully functioning healthcare language LLM involves more than simply developing the correct model. We deploy RAG (retrieval-augmented generation), human review processes, validation of the output, audit logging, and guardrails.
5. Monitor and Improve After Deployment
Our work doesn’t end at launch. We monitor model performance, validate new model versions before rollout, and re-evaluate accuracy, safety, and compliance as clinical workflows and AI models evolve.
Real Life Case Study
Our client, a multi-site clinic network, was facing a backlog: clinicians were losing hours each week to discharge summaries and prior authorization paperwork. We shortlisted a frontier, a mid-tier, and an open-weight model against the clinic’s own de-identified notes.
The frontier model scored highest on HealthBench but was priced for low-volume review, not daily use at this scale; the open-weight model kept data on-premises but needed extra tuning to match the clinic’s note formats.
Drawing on our AI clinical documentation software expertise, we deployed the mid-tier model through a cloud provider with a BAA already in place, paired with RAG and a mandatory human review step.
Within eight weeks, average discharge summary turnaround dropped from roughly 40 minutes to 15, and clinicians reported the backlog was effectively cleared during peak hours.
Common Mistakes When Choosing an LLM for Healthcare
Choosing the right large language model in healthcare is not just about picking the model with the highest benchmark score. You also need to consider compliance, real-world performance, deployment, and long-term reliability. Here are some common mistakes to avoid:
- Choosing models based only on benchmark scores. A high MedQA or HealthBench number doesn’t guarantee the model will handle your specific patient population or clinical workflow well.
- Ignoring HIPAA and BAA requirements. Deploying a model without a signed Business Associate Agreement in place is a compliance gap, not a detail to sort out later.
- Skipping real-world validation with healthcare data. A model that performs well on public benchmarks can still misfire on your actual charts, notes, and intake formats.
- Not planning for model updates and ongoing validation. Providers update models without warning, and an unvalidated version change can quietly break something that worked fine last month.
- Treating US compliance as global compliance. A HIPAA-ready deployment doesn’t automatically satisfy GDPR or the EU AI Act, and multinational buyers need both answers, not just one.
Conclusion
There isn’t one LLM in healthcare that’s right for every organization. It all comes down to what exactly you need the AI solution for, the nature of patient data, compliance needs, deployment needs, and your budget. Investing time in analyzing these aspects before the deployment may help you to prevent many future pitfalls.
If you’re planning to bring AI into your healthcare workflows, our healthcare IT consulting services can help you choose the right LLM, validate it with your data, integrate it with your existing systems, and deploy it securely while meeting healthcare compliance requirements.
FAQ
1. Which LLM is best for healthcare in 2026?
There is no ideal framework that works for all scenarios. In clinical reasoning, the best ones are Claude Opus 4.8 and GPT-5.6 Sol, but for private use cases, MedGemma and GPT-OSS-120B should be considered.
2. Is ChatGPT HIPAA compliant for healthcare use?
By default, ChatGPT does not have HIPAA compliance. OpenAI does not provide a Business Associate Agreement for the ChatGPT account; hence, it should not be used to deal with patient information.
3. What is the best open-source LLM for healthcare?
As of now, Baichuan-M3 and MedGemma 1.5 4B are great options when looking to use open-source technology. Baichuan-M3 is one of the highest-scoring open-source models in HealthBench, whereas MedGemma excels in clinical imaging tasks.
4. Can LLMs be used for medical diagnosis?
LLMs can assist in diagnosis but should never replace it. The FDA regulations consider unreviewed, time-sensitive results from diagnostic tools as medical devices; hence, many are developed to help rather than decide on care.
5. Do you need a BAA to use an LLM with patient data?
If indeed the model supplier is handling health information, then it should have a signed Business Associate Agreement under HIPAA prior to processing any patient information in an LLM.
6. What are the main use cases for LLMs in healthcare?
Usage includes clinical documentation, patient messaging sorting, coding of medical procedures, prior authorization assistance, lab reports summarization, or charting history summaries, as well as providing information to patients on health matters.
7. Are medical-specific LLMs better than general frontier models?
No, not always. While models developed specifically for medical purposes may perform well on medical-related tasks, other generic frontier models such as Claude Opus 4.8 and GPT-5.6 Sol often compare favorably to them.
8. How much does it cost to deploy an LLM in healthcare?
The cost depends on the model you choose.
- Self-hosted open-weight models have no token fees, but you pay for GPUs, infrastructure, and maintenance.
- API-based models like GPT-5.6 Sol and Claude Opus 4.8 cost up to $5.00 per million input tokens, along with any cloud usage charges.
In general, self-hosting has higher infrastructure costs, while API-based models have ongoing token costs but are easier to deploy.