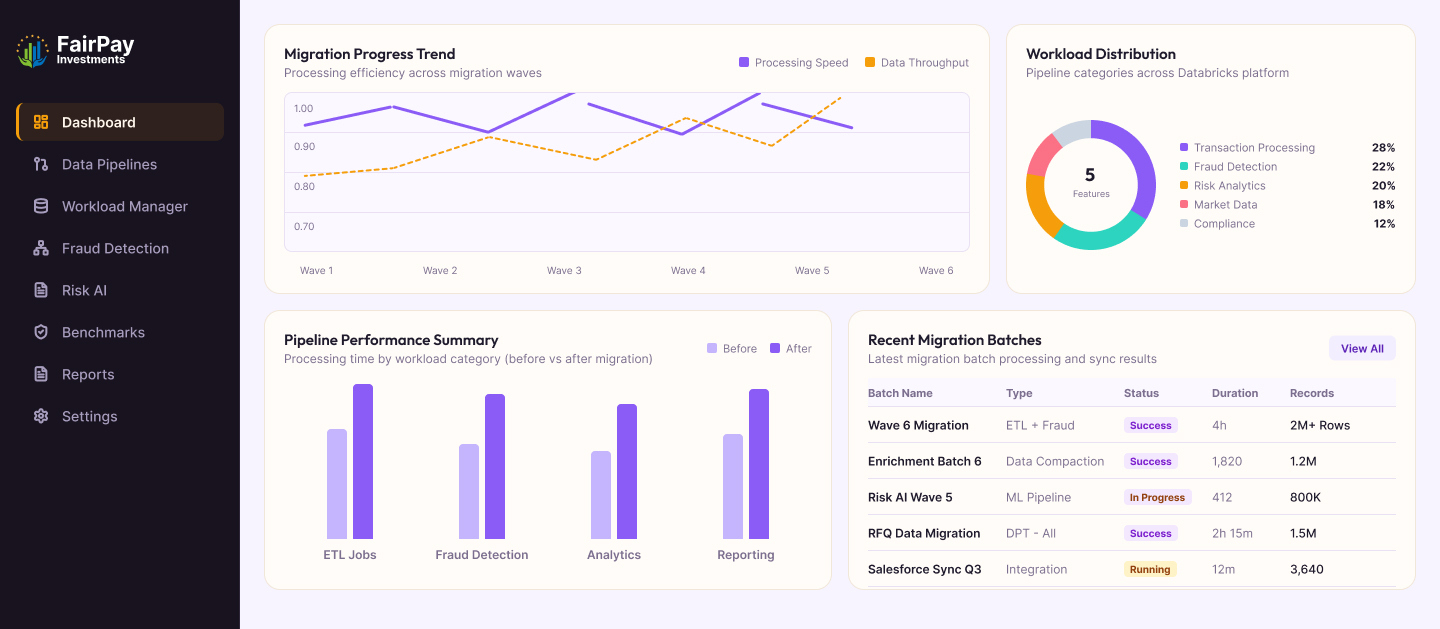
FairPay Investments, a US-based fintech company, provides capital market services, with transaction data forming a key part of its daily operations. The company had been using Hadoop for years, and its growing data volumes and large number of legacy Hive and MapReduce jobs were making data processing increasingly difficult to manage. Their fraud detection workflows also ran in batches, limiting access to recent transaction data for fraud analysis. Bacancy Technology assessed the existing Hadoop environment, removed unused or outdated workloads, and moved the active data and pipelines to Databricks on AWS. The new setup helped FairPay Investments achieve faster data processing and near-real-time fraud detection, while allowing the company to retire its Hadoop environment with near-zero downtime.
Audited Hive and MapReduce jobs and removed unused workloads.
Migrated Hadoop data and pipelines to Databricks.
Rebuilt active pipelines with Spark, Delta Lake, and Auto Loader.
Decommissioned the Hadoop cluster smoothly.
The Hadoop cluster had been running for years as the fintech client's main data processing environment. Transaction volumes had grown, but the cluster and its batch jobs were not keeping pace. Processing was taking longer, and the delay was affecting the other workloads that depended on fresh transaction data.
The Hadoop environment contained a large number of Hive and MapReduce jobs, but there was limited documentation around their dependencies. This made it difficult for the team to determine which workloads were still required and which could be removed as the data environment continued to grow.
The client's data processing work depended on Hive and MapReduce jobs that were difficult to maintain and modify. Most of the processing logic was connected to the existing Hadoop environment, so changes to data workflows required updates to the legacy jobs and their related processes.
The fintech client wanted to modernize its data environment without simply recreating the existing Hadoop setup on a new platform. Years of accumulated jobs and processing logic had made the environment difficult to manage, and moving everything without reviewing it would have carried the same complexity into Databricks.
With the help of our Databricks migration team, we moved the required Hadoop data and active workloads to Databricks on AWS. We rebuilt the processing jobs in Apache Spark and reworked the batch workflows to handle the higher transaction volumes without the same processing delays.
Bacancy Technology’s data engineers reviewed the Hive and MapReduce jobs across the Hadoop cluster and traced their dependencies to identify the workloads still in use. We removed the jobs that were no longer required and documented the active workloads before moving them to Databricks.
Our Databricks developers rebuilt the active Hive and MapReduce processing in Apache Spark on Databricks. We moved the processing logic out of the legacy Hadoop jobs and used Delta Lake for the migrated data, making the workflows easier to modify as new data and processing requirements were introduced.
The client’s IT team worked with our fintech IT team to review the existing Hadoop workloads and determine what should move to Databricks. We kept the migration focused on active business workloads rather than recreating the entire Hadoop environment, and retired the remaining Hadoop infrastructure after validating the migrated pipelines.
Incremental ingestion of transaction data using Auto Loader on Databricks.
Apache Spark processing for high-volume transaction & data workloads.
Delta Lake tables for storing and processing the migrated Hadoop data.
Near-real-time transaction processing for fraud detection workflows.
08
December 2025 - August 2026
55% reduction in batch processing time for transaction data workloads.
Near-real-time fraud detection, replacing the previous batch-based processing cycle.
100% migration of active data processing workloads from Hadoop to Databricks.
Unused workloads removed, reducing the jobs carried into the new environment.
Near-zero downtime during the transition from Hadoop to Databricks on AWS.
Hadoop infrastructure fully retired after the migrated pipelines were validated.
| Data Platform | DatabricksHadoop |
| Data Processing | Apache SparkMapReduceHive |
| Data Storage | Delta Lake |
| Cloud | AWS |
| Data Ingestion | Auto Loader |
| Data Analytics | Power BI |
| Programming | Python |
Get access to an experienced team of developers and engineers from Bacancy, handpicked to ace your goals. Kickstart within 48 hours, no-risk trial.
Years of Business Experience
Happy Customers
Countries with Happy Customers
Agile Enabled Employees