Overview

Triventa Finance, a US-based financial services firm, was struggling to assess credit risk across a wide portfolio of clients. The firm’s existing processes were heavily dependent on manual analysis and legacy credit scoring models, leading to delayed decision making and inconsistent risk evaluation. Triventa Finance collaborated with Bacancy Technology to develop an advanced data modeling platform that leverages predictive analytics, machine learning, and real-time data to optimize credit risk analysis. As an extension of the original engagement, We migrated Triventa’s data infrastructure to Snowflake, consolidating storage, transformation, and analytics onto one elastic, cloud-native platform on their existing AWS footprint.

Technologies Used

Snowflake
Python
PostgreSQL
Scikit-learn
AWS
Docker
Tableau
Power BI

Project Highlights

checkmark

Optimized credit risk scoring with predictive modeling.

checkmark

Reduced manual effort and increased speed of loan approvals.

checkmark

Integrated real-time data pipelines for dynamic risk evaluation.

checkmark

Migrated to Snowflake for a scalable, unified data platform.

Challenges & Solutions

1

Credit scoring ran on manual analysis and older fixed models. These models did not adjust to changes in borrower behavior or the market, so risk decisions were slow and often came out differently for every reviewer.

2

Preparing data for analysis took a lot of manual work. Triventa's team pulled and cleaned the financial data on their own. This slowed the process down, added errors, and often left scoring based on figures that were already out of date.

3

With a growing client base, the number of credit assessments to run each day also grew in volume. The platform had to handle heavier workloads and more users at the same time, and the original setup slowed down whenever demand spiked, or several teams ran analysis at once.

4

The client’s data lived across a PostgreSQL database and separate processing and reporting tools. No single source brought it together, so every new report or dataset meant combining data from several systems, and this got harder as the firm added more clients.

Solutions by Bacancy

1

Our data scientists built machine learning models that score credit risk automatically. The models learn from past and current financial data and adjust as borrower behavior and the market change, so scoring stays consistent across reviewers and decisions come faster.

2

Bacancy Technology’s data engineers built automated pipelines that pull, clean, and process the financial data as it comes in. This took the manual work off the client’s team, cut the errors that came with it, and kept scoring based on current figures instead of stale ones.

3

We ran the analytics on AWS cloud infrastructure and used Docker containers to package the services. This handled the heavier workloads and multiple users at once, so performance held up even when demand spiked or several teams ran assessments together.

4

Our Snowflake migration experts brought Triventa’s scattered data together in Snowflake, which runs on the same AWS infrastructure. Storage, processing, and analytics now sit on one platform, so reports and new datasets no longer need combining across separate systems.

Core Features

checkmark

Predictive Credit Risk Models

checkmark

Automated Data Pipelines

checkmark

Real-Time Risk Scoring and Insights

checkmark

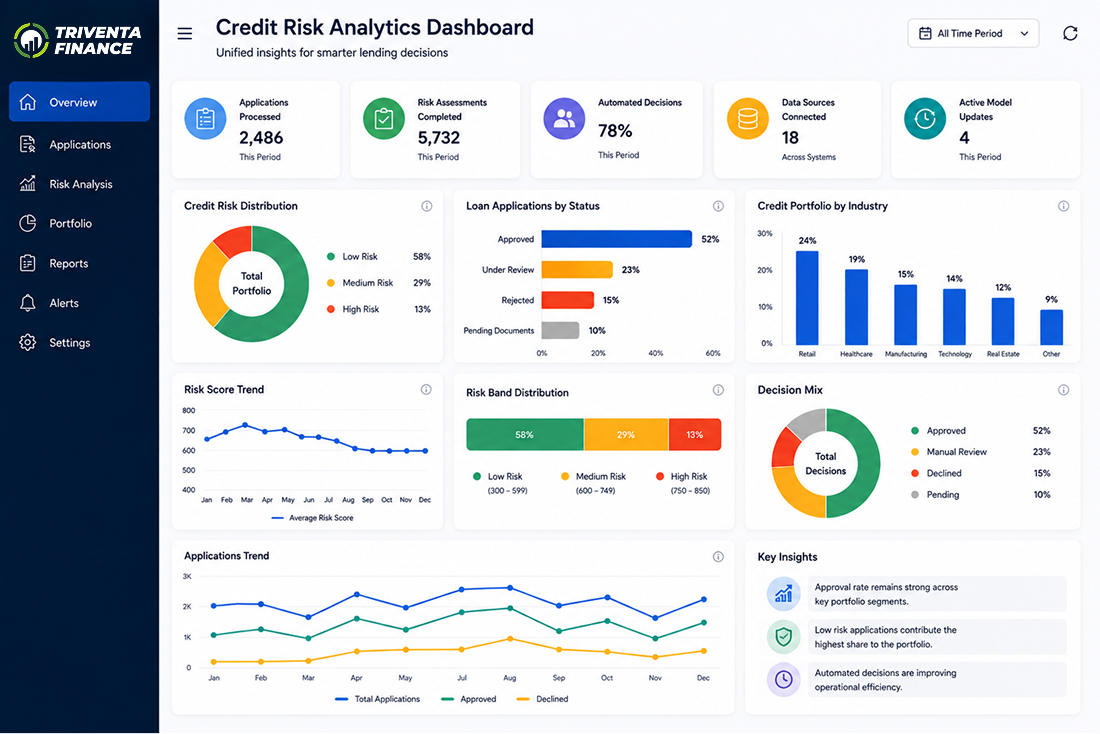
User Friendly Dashboards

No. of Resource

06

No. of Resource

Time Frame

January 2025 - July 2026

Time Frame

Project Snapshot

Triventa Finance Dashboard

Outcomes

23% more accurate risk scoring than the client's earlier manual scorecards.

55% faster credit decisions than the previous manual review process.

30 mins taken to produce a risk score, down from 8+ hours spent in manual review earlier

A drop of 78% in inconsistent scores, with every application run through the same model instead of different reviewers.

A PostgreSQL database and separate processing and reporting tools consolidated into one Snowflake platform.

88% less time spent on manual data preparation after automated pipelines replaced manual data cleansing work.

Technical Stack

Programming Languages PythonSQL
Machine Learning Scikit-learn
Data Platform Snowflake
Database PostgreSQL
Cloud and Containerization AWSDocker
Data Visualization and BI Power BITableau
Data Pipelines Automated pipelines (Python)

Experience With Bacancy

2500+ Projects Experienced Innovation with Bacancy!

Get access to an experienced team of developers and engineers from Bacancy, handpicked to ace your goals. Kickstart within 48 hours, no-risk trial.

Book a 30 min call

14+

Years of Business Experience

1458+

Happy Customers

12+

Countries with Happy Customers

1050+

Agile Enabled Employees