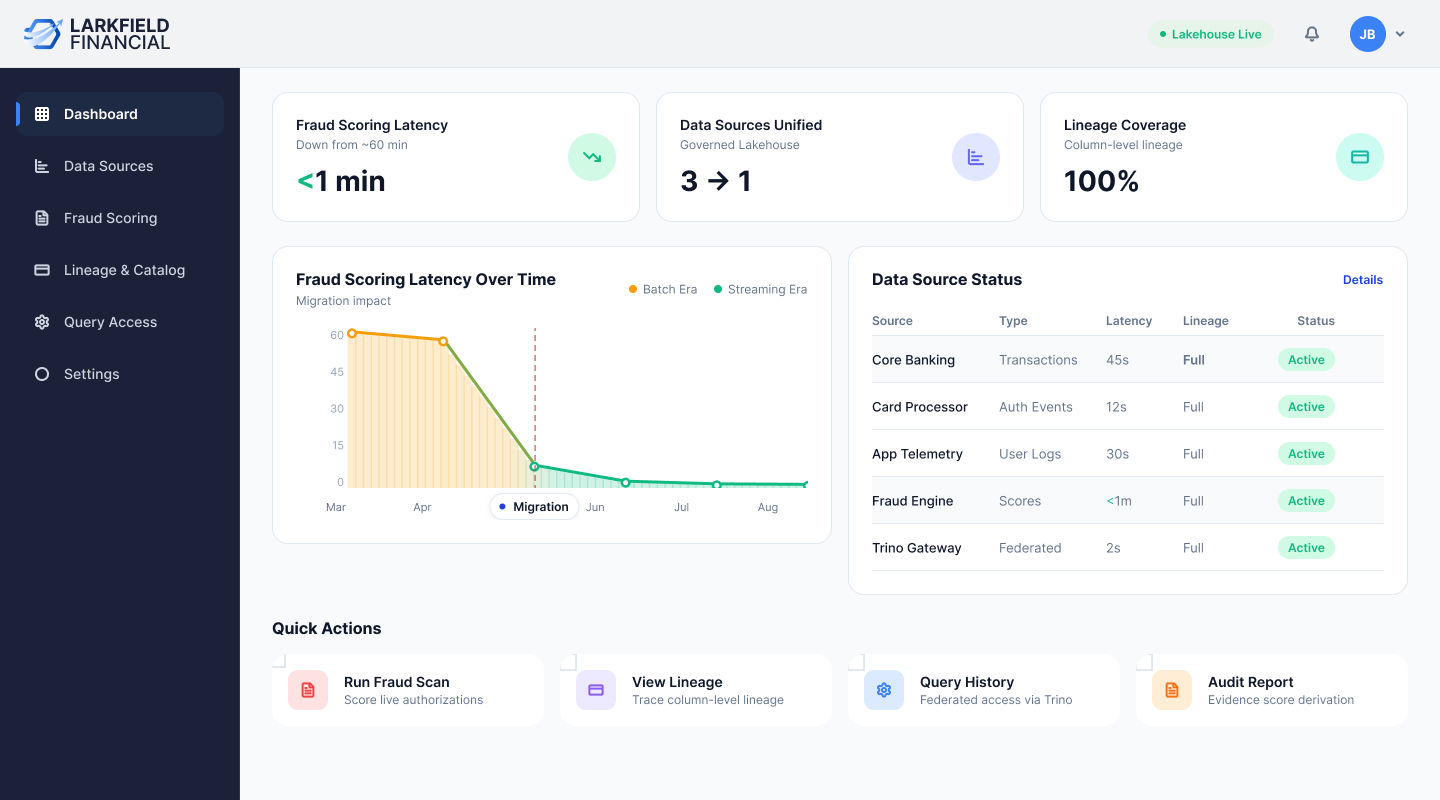
Larkfield Financial is a US consumer lending and card issuing firm. Its transaction records sat in core banking, authorization events came from the card processor, and application telemetry lived in a separate log store, each landing on its own refresh cycle. Fraud scoring ran as an hourly batch job against copies of that data, so a suspicious authorization was flagged well after the transaction cleared. Risk and compliance had a second problem: there was no lineage across the estate and no unified access control, so neither team could evidence how a given score had been derived or who had queried customer data. Multi-year history needed for audit and model training was expensive to keep queryable, and retention kept getting trimmed to hold costs down. Bacancy Technology consolidated the three sources into a governed streaming lakehouse on Delta Lake, moved ingestion onto Apache Kafka, and placed the catalog, lineage, and access control under Unity Catalog. Fraud scoring now runs against streaming data on authorization, and years of history stay queryable on low-cost storage.
Three fragmented sources merged into one governed lakehouse
Hourly batch fraud scoring replaced with near real-time scoring
Column-level lineage and unified access control across every table
Years of transaction history kept queryable on low-cost storage
Transaction records, authorization events, and application telemetry sat in three separate systems on three refresh cycles. Analysis spanning all three started with manual extracts, and the fraud scoring copies were stale by the time they were queried.
Fraud scoring ran as an hourly batch job. A flagged authorization surfaced up to an hour after it cleared, which put the review team in the position of investigating completed transactions rather than intervening on pending ones.
There was no lineage or unified access control across the estate. When a regulator or an internal reviewer asked how a particular risk score had been derived, the answer required tracing transformations by hand, and there was no single record of who had accessed customer-level data.
Multi-year transaction history was needed for audit response and model training, but keeping it queryable was expensive. Retention windows were cut back to control spend, which weakened audit coverage and left model training working from a shorter history than the risk team wanted.
We mapped the three source systems and designed raw, curated, and serving zones on Delta Lake as part of our data lake consulting services. Delta Lake gave the platform schema evolution, ACID writes, and time travel, so a table can be corrected or replayed to an earlier state without duplicating it, and streaming and batch workloads read from the same tables rather than separate copies.
Our data engineering services cover streaming ingestion, and we replaced the hourly batch jobs with Apache Kafka topics feeding Spark Structured Streaming into the raw zone. Authorization events, transaction records, and application telemetry now arrive continuously, and the fraud model reads from the curated zone within seconds of an authorization rather than at the top of the next hour.
Under our data governance services, we registered every table in Unity Catalog with an owner, business definition, and column-level lineage back to its originating system. Access permissions apply at table and column level, so cardholder identifiers and account balances are restricted by role, and every query against customer-level data is written to an audit log the compliance team can search directly.
We connected Trino to the serving zone for federated querying across zones without moving data, and set tiered retention across the lakehouse, with recent data on hot storage and older partitions on low-cost object storage that stays queryable for audit response and model training. Risk dashboards and the retention policy are maintained day-to-day by a dedicated Databricks developer from our team.
Governed medallion zones on Delta Lake for streaming and batch
Kafka and Structured Streaming replacing hourly batch ingestion
Unity Catalog lineage, role-based access, and query audit logging
Tiered retention keeping years of history queryable through Trino
05
May 2025 to December 2025
Fraud scoring latency cut from up to an hour to under a minute
Three fragmented sources consolidated into one governed lakehouse
Every table carrying column-level lineage back to its source system
Risk teams able to evidence score derivation and data access
Years of transaction history retained instead of being trimmed
Trino giving analysts federated query access without copying data
| Lakehouse platform | Databricks |
| Table format | Delta Lake |
| Streaming | Apache KafkaSpark Structured Streaming |
| Catalog and lineage | Unity Catalog |
| Query engine | Trino |
| Data processing | PySpark |
| Machine learning | PythonScikit-learn |
| Model tracking | MLflow |
| Orchestration | Databricks Workflows |
| Security and governance | Unity Catalog access controlIAM |
| Version control and CI/CD | GitGitHub Actions |
Get access to an experienced team of developers and engineers from Bacancy, handpicked to ace your goals. Kickstart within 48 hours, no-risk trial.
Years of Business Experience
Happy Customers
Countries with Happy Customers
Agile Enabled Employees