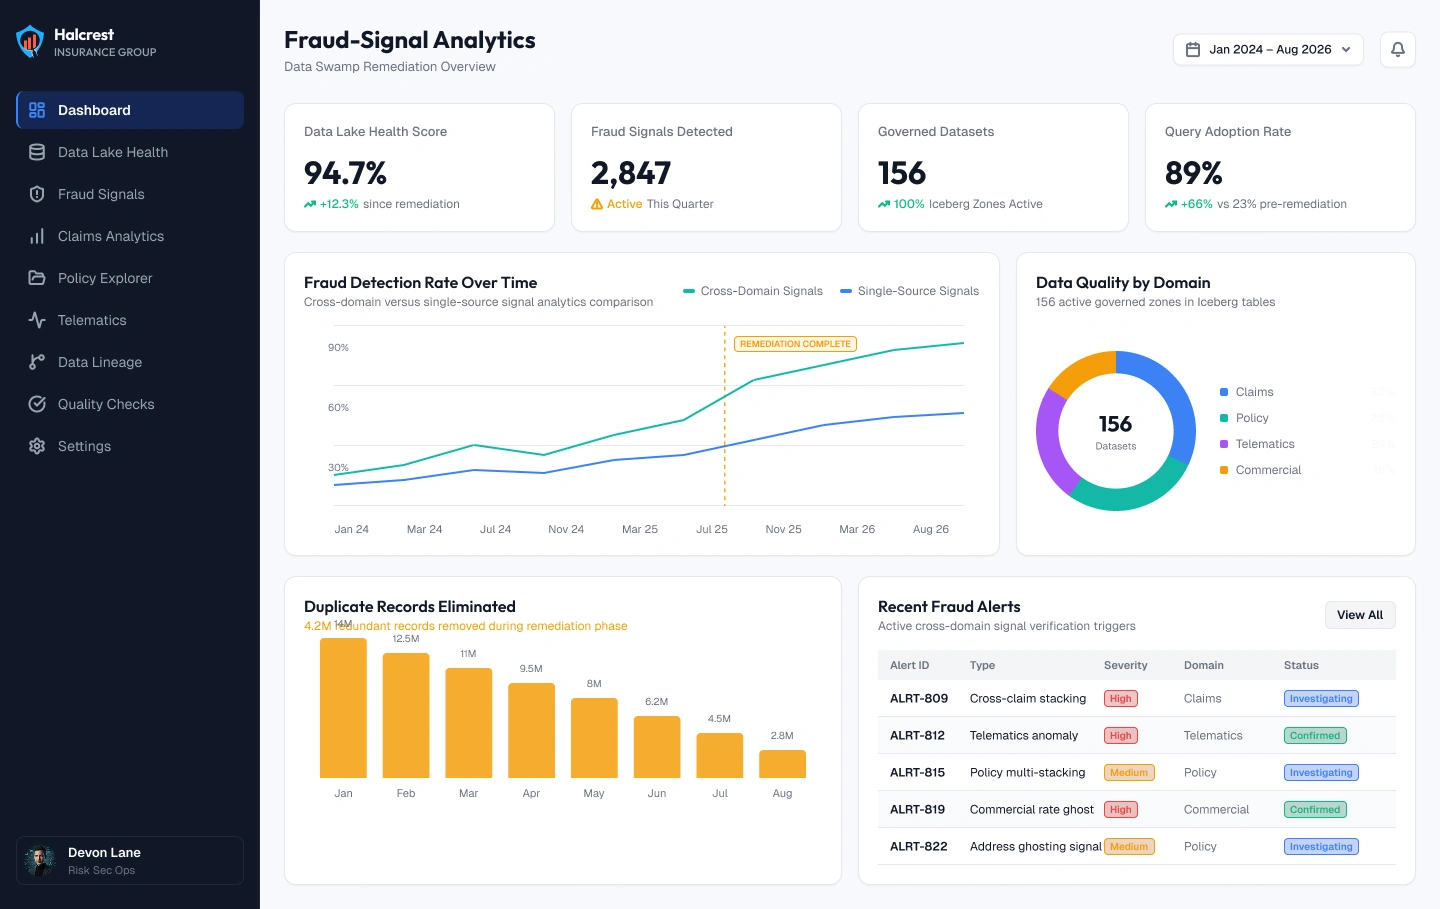
Halcrest Insurance Group is a US insurer writing auto, home, and commercial lines. It had built a data lake on Amazon S3 over several years, but writes were never governed, so claims extracts, policy snapshots, and telematics feeds accumulated as overlapping copies with no owner, no lineage, and no way to tell which version was current. Actuaries and the special investigations unit stopped querying it and went back to pulling spreadsheets from source systems, which meant fraud patterns spanning claims, policy, and telematics data were never examined together. Bacancy Technology remediated the lake in place rather than rebuilding it, adding governed Iceberg zones, a working catalog with lineage, and automated quality checks over the data already sitting in S3. Analysts now query one trusted dataset per domain and run fraud-signal analysis directly against the lake instead of reconstructing it by hand.
Ungoverned S3 lake remediated in place, with no rebuild and no migration
Claims, policy, and telematics data re-ingested through governed zones
Every dataset cataloged with an owner, column-level lineage, and quality gates
Fraud-signal analysis moved from manual exports to self-serve queries
Years of unmanaged writes left the lake full of duplicate claims and policy extracts. The same dataset existed in several prefixes under different naming conventions, with nothing recording which one was current, so two analysts querying the same subject returned different numbers.
The lake had no catalog or lineage. Teams could not confirm where a file originated, who owned it, or whether it had already been transformed upstream, which left every result requiring manual verification before anyone would act on it.
No quality controls ran at ingestion. Schema drift in claims extracts and interrupted telematics feeds went undetected for weeks, surfacing only when a downstream report looked wrong, and by then the affected period had already been reported on.
Fraud analysis depended on manual spreadsheet exports. Claims, policy, and telematics data could not be joined reliably in the lake, so patterns that only appear across all three, such as repeat claimants across separate policies, went unexamined.
We audited what was already in S3 under our data lake consulting services, identified the authoritative copy of each dataset, and designed raw, curated, and serving zones backed by Apache Iceberg tables. Iceberg gave the lake schema evolution, snapshot isolation, and time travel, so a table can be corrected or rolled back without leaving another orphaned copy behind. Nothing was migrated to a new platform, and existing storage stayed in place.
As part of our data governance services, we registered every table in AWS Glue Data Catalog with a named owner, business definition, and column-level lineage back to its source system. AWS Lake Formation applies access permissions at table and column level, so policyholder identifiers and payment fields are restricted by role, and duplicate prefixes were retired once their lineage confirmed they were superseded.
Through our AWS automation services, we built Glue jobs that deduplicate records at ingestion and validate each feed against expected schema, row counts, and value ranges before it reaches the curated zone. Failed batches are quarantined and flagged rather than published, so a broken telematics feed or a changed claims field is caught the day it happens instead of weeks later in a report.
We modeled the serving zone for analysis and connected it to Amazon Athena for self-serve querying and to Power BI dashboards maintained by a dedicated Power BI developer from our team. The special investigations unit now runs cross-domain fraud signals directly against the lake, joining claim history, policy records, and telematics on a single trusted record per policyholder and vehicle.
Governed Iceberg zones layered over existing S3 storage
Catalog with named ownership, definitions, and column-level lineage
Automated deduplication and validation gates at ingestion
Self-serve Athena queries and fraud-signal dashboards
04
April 2025 to November 2025
One authoritative dataset per domain, replacing several overlapping copies of claims and policy data
Fraud-signal analysis moved from manual spreadsheet exports to self-serve queries against the lake
Claims, policy, and telematics data joinable in a single governed query for the first time, with no manual exports
Broken feeds and schema drift caught at ingestion instead of surfacing in published reports
Storage footprint reduced by retiring duplicate and superseded copies once lineage confirmed them
Every table carrying a named owner, definition, and lineage record for audit and regulatory review
| Object storage | Amazon S3 |
| Table format | Apache Iceberg |
| Catalog and lineage | AWS Glue Data Catalog |
| Data transformation | AWS GluePySpark |
| Orchestration | AWS Step FunctionsGlue Workflows |
| Query engine | Amazon Athena |
| Data quality | Great Expectations |
| BI/dashboards | Power BI |
| Security and governance | AWS Lake FormationIAM |
| Version control and CI/CD | GitGitHub Actions |
Get access to an experienced team of developers and engineers from Bacancy, handpicked to ace your goals. Kickstart within 48 hours, no-risk trial.
Years of Business Experience
Happy Customers
Countries with Happy Customers
Agile Enabled Employees