Overview

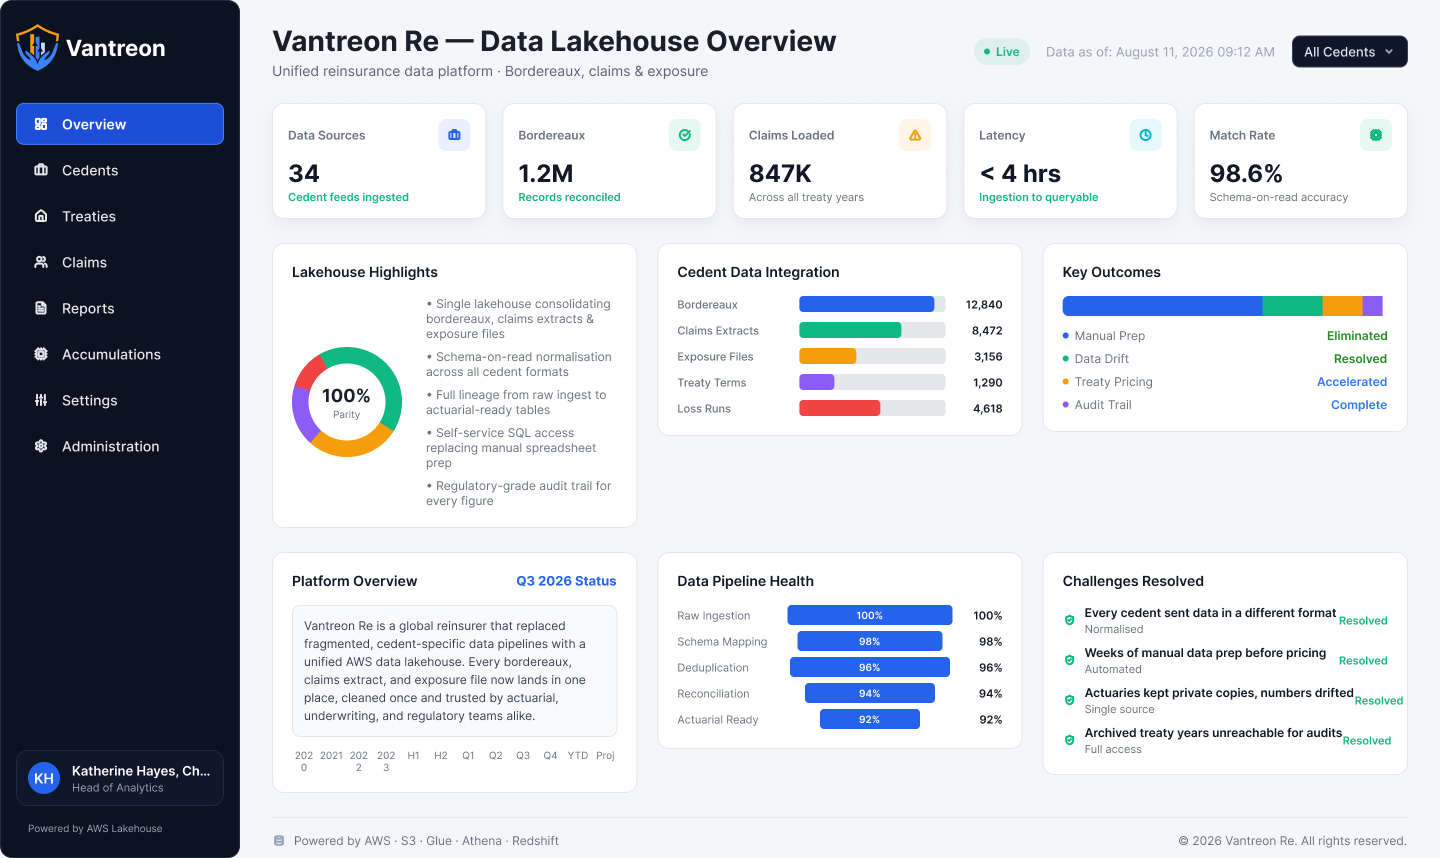
Vantreon is a reinsurance firm, and it lives or dies on its data. This one was buried under it. Every cedent it worked with sent data a different way: bordereaux as spreadsheets, claims as extracts, exposure files in their own layouts, none of it lining up with the next. Before anyone could price a treaty or run an accumulation, someone had to spend weeks pulling all of it into shape by hand. Actuaries kept private copies, numbers drifted between teams, older treaty years got archived off where nobody could reach them, and every regulatory cycle became a hunt to prove where each figure came from. Vantreon needed one place to hold all of it, cleaned once and trusted by everyone. We built that place as a data lakehouse on AWS.

Technologies Used

Amazon S3
AWS Glue
Python
Amazon Athena
Apache Iceberg
Apache Iceberg

Project Highlights

checkmark

Single AWS Lakehouse For Every Cedent Data Source

checkmark

Messy Bordereaux Turned Into One Curated Model Now

checkmark

Direct Query Access For Actuarial And Pricing Work

checkmark

Full Data Lineage Kept For Each Reporting Cycle Run

The Challenges

1

Cedent data arrived from dozens of sources in dozens of shapes: bordereaux spreadsheets, claims extracts, exposure files, each cedent formatting things its own way. Getting one clean view across all of them meant weeks of manual wrangling before any analysis began.

2

Actuaries and pricing teams needed the same underlying data, but each pulled their own copy and reshaped it locally. Numbers drifted between teams, nobody was sure which extract was current, and reconciling two reports often took longer than producing them did.

3

Exposure and accumulation analysis needs history, but the old warehouse could not hold the volume, so older treaty years got archived off and went dark. Answering a question that spanned several years meant restoring that data before anyone could even start the work.

4

Regulators and rating agencies expect data that traces back to its source, and the patchwork of copies and manual edits made that hard to prove. Every reporting cycle turned into a scramble to show where each number came from and that nothing had been quietly altered.

Solutions by Bacancy

1

We put S3 right at the bottom of the whole system, as the one central place every cedent file always lands. Bordereaux, claims, exposure data, it all comes in raw and stays raw. Our AWS developers wired up the ingestion so a file shows up, gets catalogued, and can be queried right away, nobody ever reshapes it first. The original always sits there completely untouched, no matter whatever gets built above it.

2

Above that raw layer is where the mess gets sorted out. Our data engineers built the part that reads those different cedent files and lines them up into one shape. A bordereau from one cedent lands in the same fields as the next, claims connect to the right treaties, exposure matches across years. So instead of ten people keeping ten versions, everyone pulls the same clean set.

3

With the data structured, we opened it up for analysis without ever moving it around again. Actuaries and pricing teams query the curated layer directly for exposure, accumulation, and pricing work, and the BI dashboards read from the very same place. Because everyone hits one source, two teams asking the same question now get the same answer instead of two different ones.

4

Governance got built in rather than bolted on afterward. Every file keeps its lineage from the moment it lands, access is controlled by role, and history stays retained instead of archived. This is what our insurance IT services are built on. When a regulator or rating agency asks where a number came from, the firm traces it straight back to the original cedent file, no scramble and no restoring old data.

Core Features

checkmark

S3 Landing Zone For Raw Bordereaux And Claims Data

checkmark

Curated Layer Mapping Cedents To One Shared Model

checkmark

Direct Query Access For Actuarial And BI Teams Now

checkmark

Built-In Lineage, Role Access, And Data Retention

No. of Resource

05

No. of Resource

Time Frame

February 2025 - July 2025

Time Frame

Project Snapshot

vantreon

Outcomes

1 AWS lakehouse now holds every cedent's data, replacing dozens of scattered files and extracts.

6 weeks of manual data wrangling per cycle dropped to a curated set ready to query on landing.

100% of curated numbers now trace back to the original cedent file for regulators and auditors.

10+ treaty years now stay queryable at once, with no restoring of archived data before analysis.

1 source now feeds actuaries, pricing, and BI, so two teams no longer get two different answers.

0 private data copies remain, since every team now queries the same curated lakehouse directly.

Technical Stack

Cloud Infrastructure Amazon Web Services (AWS)
Storage Layer Amazon S3Amazon S3 Glacier
Table Format Apache Iceberg
Data Cataloging and ETL AWS Glue
Query Engine Amazon AthenaAmazon Redshift
Governance and Access AWS Lake Formation
Data Processing Python (PySpark)Apache Spark
Business Intelligence Amazon QuickSight
Project and Issue Tracking Jira

Experience With Bacancy

2500+ Projects Experienced Innovation with Bacancy!

Get access to an experienced team of developers and engineers from Bacancy, handpicked to ace your goals. Kickstart within 48 hours, no-risk trial.

Book a 30 min call

14+

Years of Business Experience

1458+

Happy Customers

12+

Countries with Happy Customers

1050+

Agile Enabled Employees