Quick Summary
Through this guide, you’ll understand how to plan and migrate from Snowflake to Databricks. From analysing the current environment to choosing the right workloads, managing costs, governance, testing, and production cutover, you will explore when Databricks is the better fit, when keeping Snowflake makes sense, and when a hybrid approach can work better for enterprise workloads.
Table of Contents
Introduction
For data engineering teams, the problem is not limited to choosing between Snowflake and Databricks. The analytics teams may be using Snowflake for reporting and BI, while data engineering and AI teams might prefer Databricks for data processing, machine learning, or generative AI. This can work in some cases, but it can also create multiple copies of the same data, additional pipelines, higher infrastructure costs, and more work to keep data consistent across platforms. For organizations dealing with such challenges, choosing a single platform can be a solution
That’s the reason why the right Snowflake to Databricks migration strategy is not only about moving everything. There are some workloads that benefit from Databricks, others may require redesign, and some may be better left on Snowflake. The real challenge is understanding the existing Snowflake environment, identifying workload dependencies, comparing performance and costs, and determining where Databricks provides a meaningful architectural or business advantage.
So, let us understand how to make the move, the pitfalls to avoid, the cost factors to consider, and whether you should run them both together.
Why Enterprises Consider Snowflake to Databricks Migration
No one is looking to replace an existing data platform simply because a newer one exists. In most enterprise Snowflake to Databricks migration projects, the decision is driven by specific operational or architectural limitations, duplicated data, and disconnected AI and analytics workflows. The business case for migrating from Snowflake to Databricks usually comes from a combination of factors rather than a single reason.
Unifying Analytics and AI/ML Workloads
Many enterprises use Snowflake as their primary analytical warehouse. But their Data engineering and data science teams rely on separate Spark environments, cloud ML services, or specialized AI infrastructure to move data between systems before it can be transformed, enriched, and used for feature engineering.
The separation creates several problems, such as data duplication, pipeline overhead, lineage gaps, logic duplication, data freshness issues, and governance complexity. Databricks can consolidate many of these workloads around a common data platform. Data engineering, SQL analytics, notebooks, machine learning, and AI workloads can operate against governed data without requiring every team to maintain an independent copy. The objective is not simply to put more workloads on Databricks. It is to reduce the distance between the data and the engineering processes that prepare it.
Managing Compute Costs for Heavy Data Workloads
The cost becomes a migration driver when organizations have workloads that do not fit neatly into traditional warehouse usage patterns. Snowflake’s consumption-based warehouse model can be effective for BI, interactive SQL, and workloads where teams value simplicity and predictable resource management. However, large-scale transformations, complex joins, repeated processing, extensive ML workloads, and long-running engineering jobs can create a different cost profile.
Databricks provides a different model by combining platform-level DBU charges with the underlying cloud infrastructure. This gives engineering teams more control over compute configuration, including instance types, job clusters, autoscaling, and workload-specific resource allocation. However, Databricks should not be assumed to be cheaper by default, as inefficient Spark jobs, oversized clusters, idle resources, excessive shuffles, poor partitioning, and unnecessary data processing lead to high costs.
Handling Real-Time Streaming and Unstructured Data
Businesses need to process more than structured warehouse data, real-time events, application logs, IoT data, documents, images, audio, and other unstructured data requiring processing patterns that extend beyond traditional SQL analytics. When these workloads are split across Snowflake and Databricks, separate streaming systems, object storage, and specialized processing environments, teams can end up managing additional pipelines and data copies.
Databricks enables streaming to large-scale data processing and unstructured data workloads in the same lakehouse environments. With cloud object storage, Delta Lake, Structured Streaming, and native support for AI and machine learning workflows, teams can process and transform diverse data types without moving everything into a separate analytics environment. This is valuable for organizations that are building real-time analytics, recommendation systems, document processing, or GenAI applications along with traditional data workloads.
A Snowflake to Databricks migration can help organizations build a more portable architecture by separating the data layer from the processing and consumption layers. With data stored in cloud object storage and managed through open table formats such as Delta Lake, organizations can design architectures where multiple workloads and processing engines can interact with the same data. This can make it easier to introduce new technologies, change compute strategies, or support specialized workloads without rebuilding the entire data outlook.
Snowflake vs Databricks: Architectural Differences That Shape the Migration
A successful migration starts with understanding that Snowflake and Databricks are built around different architectural models. Snowflake is designed as a highly managed cloud data platform, and Databricks is built around the lakehouse model, combining data engineering, analytics, machine learning, and AI workloads. That difference between Snowflake vs Databricks affects far more than where tables reside. It determines how data is stored, how compute is provisioned, how pipelines are built, and how much platform engineering your team will need after the migration.
| Capability
| Snowflake
| Databricks
| Who Wins?
|
|---|
| Core architecture
| Managed warehouse; data stored in Snowflake-controlled micro-partitions
| Lakehouse over your own S3/ADLS/GCS buckets, governed by Unity Catalog
| Databricks for control and portability
|
| Storage format
| Proprietary FDN format, with Iceberg tables now supported
| Delta Lake and Iceberg as first-class, readable by any engine
| Databricks |
| Compute model
| Virtual warehouses in T-shirt sizes, per-second billing, auto-suspend
| Job clusters, SQL warehouses, and serverless with Photon; instance-level tuning
| Snowflake for simplicity, Databricks for cost ceiling
|
| SQL and BI performance
| Mature optimizer, near-zero tuning, very consistent concurrency
| Databricks SQL with Photon and liquid clustering; strong but needs configuration
| Snowflake, narrowly, for pure BI
|
| Data engineering and ETL
| Snowpark, Streams, Tasks, Dynamic Tables
| Native Spark, Lakeflow Declarative Pipelines, Auto Loader
| Databricks
|
| ML, GenAI, and serving
| Snowflake ML, Cortex, Container Services
| MLflow, Mosaic AI, Model Serving, Vector Search, Agent Framework
| Databricks, clearly
|
| Streaming ingestion
| Snowpipe Streaming, Dynamic Tables
| Structured Streaming, Auto Loader, real-time mode
| Databricks
|
| Governance model
| RBAC, row access policies, dynamic masking, Horizon
| Unity Catalog covering tables, files, models, dashboards, and AI assets
| Databricks for breadth, Snowflake for simplicity
|
| Admin overhead
| Minimal; almost no platform engineering required
| Real platform engineering required for clusters, policies, and tuning
| Snowflake |
Key Steps to Follow in a Snowflake to Databricks Migration
Snowflake to Databricks migration takes more than moving data and converting SQL. It needs to follow a clear process to assess the Snowflake environment, plan the Databricks architecture, migrate the right workloads, validate performance, control costs, and reduce disruption.
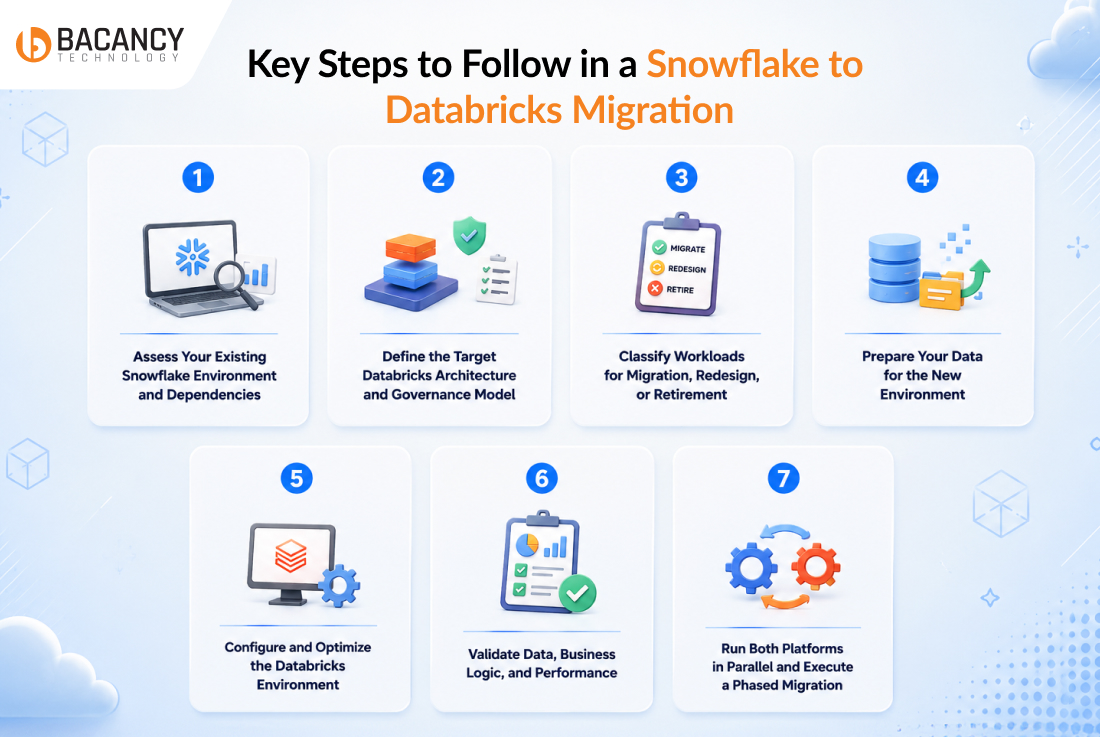
1. Assess Your Existing Snowflake Environment and Dependencies
Databricks migration is rarely determined by how quickly data can be moved. It depends on whether the team understands the existing environment, defines the target architecture, identifies dependencies, and validates workloads before switching production traffic.
Start by creating a complete inventory of the Snowflake environment. Then review account usage, query history, warehouse usage, tables, views, stored procedures, UDFs, tasks, streams, and other dependencies.
You can engage Snowflake developers to run the assessment for you and document the dependencies, query patterns, and workload costs that a migration plan depends on.
2. Define the Target Databricks Architecture and Governance Model
Before moving workloads from Snowflake, define how they will run in Databricks. You need to design the target architecture around data, analytics, engineering, and AI needs, and decide how storage, compute, networking, and workloads will be organized. Then establish the Unity Catalog structure, identity and access controls, data permissions, storage locations, and compute policies.
3. Classify Workloads for Migration, Redesign, or Retirement
You do not need to move everything from Snowflake to Databricks. Try to classify each workload as lift-and-shift, redesign, retire, or leave in place. The simple SQL workloads may require minimal changes, while Snowflake-specific features such as Streams, Tasks, Snowpark, and stored procedures may need to be rebuilt. Also identify unused tables, reports, and pipelines so you do not spend money migrating data that no longer provides value.
4. Prepare Your Data for the New Environment
After you are done classifying which data to migrate and which not to, the next step to follow is preparing your data before, prepare the data before loading it into Databricks and focusing on moving historical data to the target cloud storage and mapping Snowflake data types carefully, especially variant, timestamps, and high-precision numeric fields.
Set up Databricks for production before migrating critical workloads. Then configure compute policies, autoscaling limits, SQL warehouses, storage optimization, monitoring, and cost controls. Then set up Git, CI/CD, testing, and deployment processes early. A well-configured environment helps prevent unexpected performance and infrastructure costs after the migration.
The validation needs to cover three core areas such as data accuracy, business logic, and performance. You need to compare row counts, aggregates, checksums, reports, and key business metrics between Snowflake and Databricks. Then test real workloads under realistic concurrency and refresh schedules.
For critical workloads, run Snowflake and Databricks in parallel before switching production traffic. Start with lower-risk workloads, validate the results, and then move more important domains in stages. Try to keep a rollback plan for every workload and monitor data accuracy, performance, reliability, and cost to migrate from Snowflake to Databricks.
Common Pitfalls to Avoid When Migrating From Snowflake to Databricks
The migration can go wrong even when the technology works as expected. The majority of problems come from incomplete discovery, poor planning, hidden dependencies, or rushed validation. Learn about common pitfalls and how to avoid them to keep the project on budget and reduce disruption to business users.
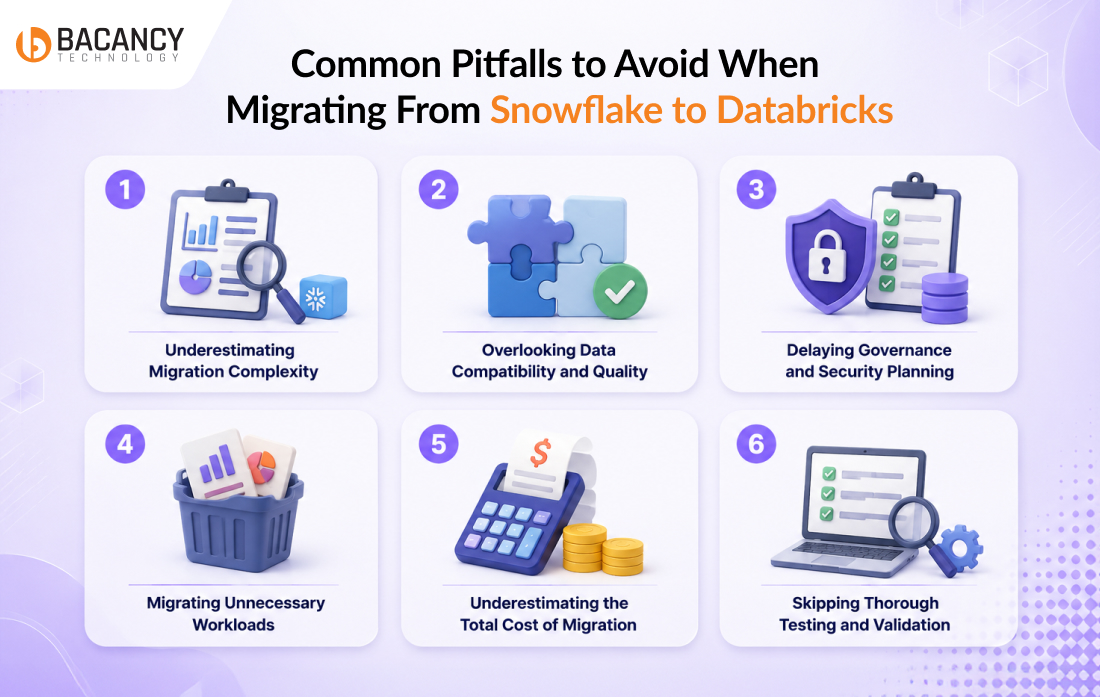
1. Underestimating Migration Complexity
Do not estimate the project by counting tables alone. The stored procedures, dbt models, Airflow DAGs, custom SQL, integrations, and undocumented business logic can add significant effort.
2. Overlooking Data Compatibility and Quality
The data types and SQL behaviour can differ between Snowflake and Databricks. The semi-structured data, timestamps, numeric precision, and schema enforcement can all create unexpected issues.
3. Delaying Governance and Security Planning
Databricks governance is not identical to Snowflake RBAC. The Unity Catalog, roles, permissions, storage credentials, and external locations need to be mapped and tested before production workloads move.
4. Migrating Unnecessary Workloads
Not every table, dashboard, or pipeline needs to be migrated. The unused or outdated workload increases migration time, testing effort, and long-term maintenance costs.
5. Underestimating the Total Cost of Migration
Migration costs go beyond the new platform bill. The factors in parallel environments include data transfer, engineering time, consultants, testing, and training, leading to temporary productivity loss. You need to calculate the full migration cost before committing to the project budget.
6. Skipping Thorough Testing and Validation
This is the most critical mistake teams make while migrating from Snowflake to Databricks. If you only check the outputs at the end, a converted pipeline that returns slightly wrong numbers goes live undetected, and the error can persist in your reports for months before anyone traces it back. Compare results between both platforms as each workload converts, and hold cutover until the numbers match across a full business cycle.
The Real Cost To Migrate from Snowflake to Databricks
The cost of a Snowflake to Databricks migration depends on many factors apart from just the data volume. The main factors include workload complexity, number of pipelines, procedures, integrations, testing, data transfer, and the time needed to run both platforms during the transition.
Assessment and Planning
Before any Snowflake to Databricks migration project, teams actually need to spend their time and resources to conduct an assessment and review workloads, dependencies, data quality, current costs, and target architecture. Effective planning helps identify hidden work early and keeps the migration budget realistic.
Pipeline and Code Conversion
The simple SQL workloads may move with limited changes, but stored procedures, UDFs, Snowpark code, dbt models, and complex pipelines often require redesign. The more Snowflake-specific the workload, the more engineering effort the migration is likely to require.
If your team is strong on Snowflake but new to Databricks, you can hire Databricks developers to work alongside them through the conversion.
Parallel Running
Most large migrations need a period where Snowflake and Databricks run together. This allows teams to compare results, test performance, and resolve issues before cutover. You need to budget for the additional compute, storage, and pipeline costs during this period.
Cloud Transfer and Egress
Moving large datasets from Snowflake to Databricks can add significant cloud costs, particularly when data crosses regions or cloud providers. Try to review your data volume, storage locations, and transfer routes before choosing the migration approach.
Training and Productivity
To migrate from Snowflake to Databricks requires learning new tools and processes, that include Spark, Delta Lake, workflows, monitoring, and cost management. It also includes training and the temporary productivity impact in your project budget.
Post Migration Optimization
The migration does not end at cutover. The teams may need to optimize queries, compute resources, storage, and pipelines after workloads go live. The budgeting for this phase helps ensure the new environment delivers the expected performance and cost.
Overall, the real cost of a Snowflake to Databricks migration comes down to how much of your code has to be rewritten rather than moved, and how long you run both platforms in parallel. The other line items are smaller and easier to estimate.
Planning to Migrate from Snowflake to Databricks?
Our Databricks consultants can help you work out what the migration will cost and handle the implementation once you decide to move.
Can You Run Snowflake and Databricks Together?
Yes. For many enterprises, running Snowflake and Databricks together can be a better long-term approach rather than a temporary migration strategy.
The key is to give each platform a clearly defined role. Snowflake can continue supporting SQL analytics, BI, reporting, and workloads where its managed experience and concurrency are valuable. Databricks can handle data engineering, large-scale processing, streaming, machine learning, and AI workloads.
A dual-platform architecture can also reduce unnecessary data duplication when both platforms work with data stored in common cloud storage and supported open table formats. However, this approach requires strong governance supporting teams that need clear ownership rules, consistent security policies, reliable data lineage, and centralized cost monitoring.
Without those controls, a two-platform strategy can simply create two sets of pipelines, policies, and operating costs. With the right architecture, however, enterprises can use each platform where it provides the most value instead of forcing every workload onto a single system.
How Bacancy Technology Can Help with Snowflake to Databricks Migration
Snowflake to Databricks migration needs the right technical expertise to handle platform differences without disrupting existing data operations. We help organizations plan, execute, and organize their migration based on their workloads, architecture, and business goals.
We at Bacancy Technology, as a leading data engineering company, deliver a migration approach tailored to the complexity of your existing Snowflake environment and the workloads you want to move to Databricks. Based on your goals, we can support the full migration or specific areas where you need expertise. Our key areas of support include:
1. Migration Assessment: We first review your Snowflake environment, workload usage, dependencies, and existing architecture to create a practical migration strategy.
2. Architecture & Roadmap: Then we design a Databricks architecture that fits your data engineering, analytics, streaming, ML, and AI requirements, with a clear roadmap for migration.
3. Workload & Code Migration: We migrate and modernize SQL, ETL pipelines, stored procedures, dbt models, and Snowflake-specific workloads, redesigning components where direct conversion is not practical.
4. Data & Governance Migration: To migrate from Snowflake to Databricks, we established Delta Lake and Unity Catalog while mapping data access, security, governance, and lineage requirements to the Databricks environment.
5. Testing & Performance Optimization: Then we validate the data, business logic, and workload performance while optimizing compute, pipelines, and storage for the target environment.
6. Phased Cutover & Support: We support parallel runs, production cutover, issue resolution, and post-migration optimization to help teams transition with minimal disruption.
If you are planning to migrate from Snowflake to Databricks, Bacancy Technology can help you make the transition with a scalable architecture, controlled costs, and minimal disruption to your existing data operations.
Frequently Asked Questions (FAQs)
Snowflake is a managed cloud data platform designed primarily for SQL analytics, BI, and data warehousing, and Databricks follows a lakehouse approach that brings data engineering, SQL analytics, streaming, machine learning, and AI workloads together.
The enterprises generally consider a Snowflake-to-Databricks migration when they want to bring analytics, data engineering, and AI workloads together. It reduces duplicated data and pipelines, gains more control over compute, or builds a more flexible data architecture, and for all of these, Databricks is usually preferable.
The migration timeline effort depends more on workload complexity and dependencies than on data volume. A smaller environment with straightforward SQL workloads may take a few months, while a large enterprise with complex procedures, pipelines, integrations, governance requirements, and critical reporting can take significantly longer.
Not necessarily. Databricks can provide cost advantages for large-scale data engineering, transformation, and machine learning workloads because teams have more control over compute resources. However, inefficient jobs, oversized clusters, idle resources, and poor optimization can increase costs.
Databricks can support a broad range of analytics, engineering, machine learning, and AI workloads, but a complete replacement is not always necessary. Some enterprises continue using Snowflake for specific BI, reporting, or SQL workloads while using Databricks for data engineering, streaming, ML, and AI.
The biggest challenge is usually platform-specific logic, rather than moving the data itself. Standard SQL can often be converted with relatively little effort, while stored procedures, Snowpark code, UDFs, and Snowflake-specific functions may require redesign.
Not always. The well-structured dbt project can be retained because dbt supports both Snowflake and Databricks. However, teams may need to change the adapter and configuration, update Snowflake-specific macros or functions, and adjust incremental models and materializations for the Databricks environment.
Both platforms provide strong access control and governance, but their models are structured differently. The Unity Catalog provides centralized governance across Databricks data and other supported assets, while Snowflake uses a mature role-based access control model with features such as row access policies and dynamic masking.
Yes, for critical workloads, running both platforms in parallel gives teams time to compare data, business logic, reports, and performance before production cutover. This is particularly important for financial, regulatory, and executive reporting.