Quick Summary
Through this blog guide, you will learn how LLM tokenization affects text processing, context usage, and AI costs. You will also explore how tokenizers work, why token usage varies across models and languages, and how to optimize costs and performance.
Table of Contents
Introduction
Unlike humans, who see a prompt as a few lines of text, an LLM sees it whole differently; it considers it a sequence of tokens. And these tokens influence how much information the model can actually process, how quickly it can respond, and how much you pay for every interaction. The same sentence can produce different token counts across models. So, making Tokenization in LLMs an important consideration when building and scaling AI applications. A support chatbot can consume maximum tokens if a long conversation is held, while a RAG application can waste valuable context by sending the entire document instead of relevant content. You know, even codes, numbers, formatting, and non-English text also affect token usage.
To control the cost of Tokenization in LLMs, you need to understand how text is broken into tokens based on context usage, latency, and application performance. The OpenAI Tokenizer provides a practical way to see how text is converted into tokens and how models learn to understand statistical relationships between these tokens. It also helps you understand how a piece of text might be tokenized by an LLM and the total count of tokens in that piece of text.
What Is LLM Tokenization?
A token is a basic unit of text that a large language model (LLM) operates in. It is not necessarily a complete word; based on the tokenizer, a token can represent an entire word, a part of a word, punctuation, whitespace, or even a byte. Tokenization in LLMs is the process of converting raw text into smaller units before the LLM model actually processes it. Having an understanding of tokenization in large language models is important because models do not process text in the same way humans read it. Instead of seeing a sentence of tokens, each token is mapped to a numerical ID based on the model’s vocabulary.
Let’s understand it through an example: The sentence “Tokenization makes AI smarter.” might be divided into ["Token", "ization", " makes", " AI", " smart", "er", "."]. Basically, seven tokens in total. These token IDs are then converted into numerical vector representations called embeddings, which the model processes through its neural network.
In other layman’s words, tokenization in large language models is the bridge between human-readable text and the numerical representation that an LLM can process. If the process reverses, it is known as detokenization, which converts the model’s output tokens back into readable text.
The LLM Tokenization Process From Training to Live Prompts
Tokenization in large language models happens in two main stages: first, the tokenizer learns how to divide text into tokens; then that learned vocabulary and tokenization process are applied whenever a user sends text to the model.
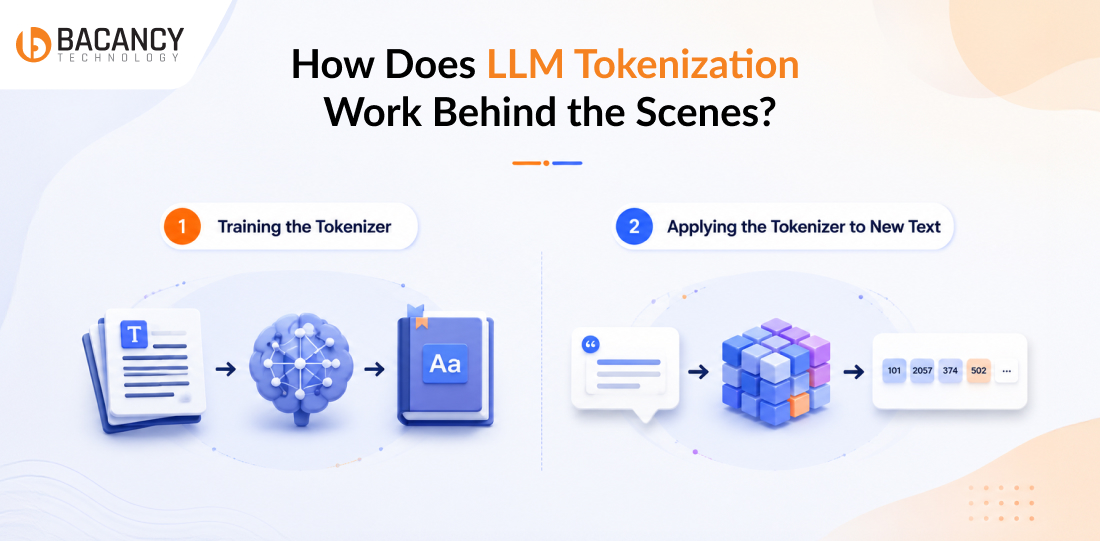
1: Training the Tokenizer
Before an LLM can process prompts, its tokenizer is built using a large and representative text corpus. The tokenizer learns how to divide text into useful, reusable pieces and stores those pieces in a fixed vocabulary. For tokenizers based on approaches such as Byte Pair Encoding (BPE), the process begins with small units and progressively combines frequently occurring sequences. For example, if t and h frequently appear together, the tokenizer can learn th as a token. If they commonly occur together, they may become another token.
This process continues till tokenizer reaches its target vocabulary size; the resulting vocabulary can contain complete words, parts of words, punctuation, whitespace patterns, and other frequently occurring text sequences.
2: Applying the Tokenizer to New Text
When you send a prompt to an LLM, the tokenizer takes the text and divides it according to the vocabulary and rules it learned during training.
For example, the sentence:
LLM tokenization makes language models work.
might be represented by a tokenizer as something similar to:
["LLM", " token", "ization", " makes", " language", " models", " work", "."]
The exact token boundaries vary by model and tokenizer. A common word may fit into a single token, while a technical term, uncommon name, misspelling, or word in another language may be split into several tokens. Each resulting token is assigned a numerical token ID. These IDs are then converted into vector representations called embeddings, which the model’s neural network can process.
The complete flow looks like this:
Text, Tokens, Token IDs, Embeddings, Model Processing, Output Tokens, Text
This is the core of LLM tokenization, which converts language into a representation that the model can mathematically process and then converts the model’s output back into readable text.
Note: Tokenization matters more as a technical preprocessing step. The way a model divides text affects how many tokens an input requires, which can influence context window usage, processing efficiency, latency, and API costs.
Build Smarter, More Cost-Efficient LLM Architecture
Hire LLM Engineers from Bacancy Technology to design, optimize, and scale production-ready LLM systems with efficient prompts, context, and model selection.
Types of LLM Tokenization Algorithms
The modern tokenization in LLMs relies on several major approaches that break text into tokens. The most important are Byte Pair Encoding (BPE), WordPiece, and Unigram, while SentencePiece provides a framework for training and applying tokenizers using methods such as BPE and Unigram.
These approaches differ mainly in how they build a vocabulary and decide which pieces of text should become tokens. You must have an understanding of differences to know why these two LLMs can tokenize the same sentence differently and why token counts can vary across model families.
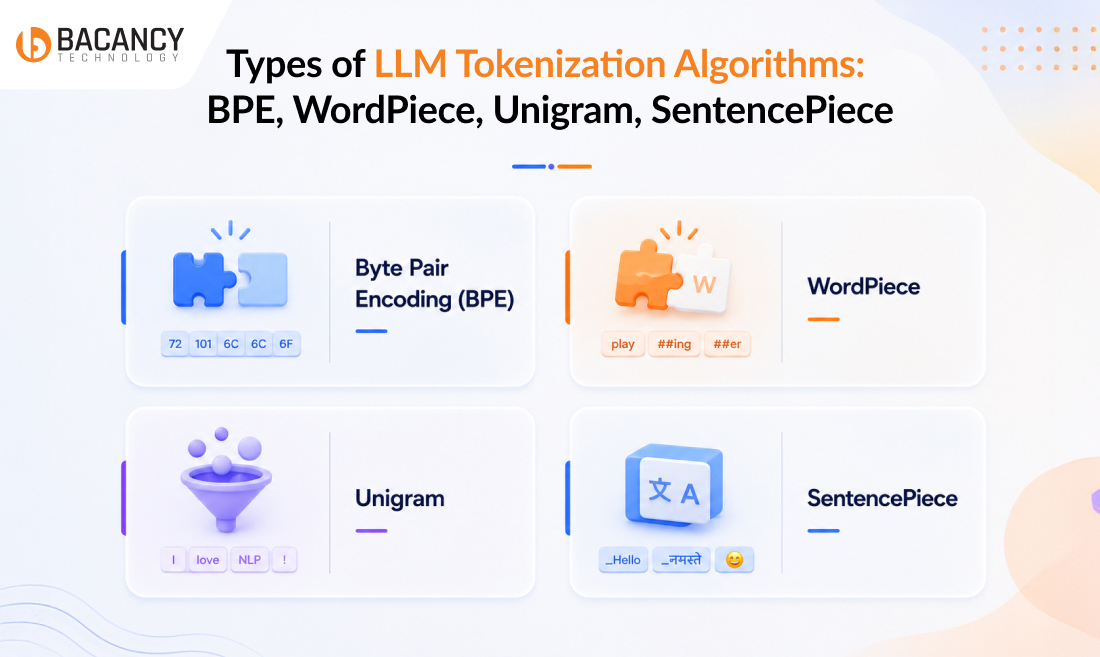
Byte Pair Encoding (BPE)
BPE is known as one of the widely used approaches in modern LLM tokenization. It starts from small units and repeatedly combines frequently occurring adjacent sequences to create larger tokens. The majority of modern implementations operate at the byte level. Byte-level BPE starts from raw bytes rather than relying only on characters, allowing the tokenizer to represent arbitrary text, including emojis, unusual symbols, and scripts that may not be well represented by a traditional character vocabulary.
WordPiece
Like BPE, WordPiece builds larger tokens from smaller pieces. However, its vocabulary-building process uses a different statistical objective. WordPiece remains important for understanding the history and development of LLM tokenization, particularly because it helped establish subword tokenization as a practical way to handle both common vocabulary and previously unseen words.
Unigram
Unigram takes a different approach from BPE and WordPiece. Instead of starting with a small vocabulary and repeatedly merging pieces, it begins with a large collection of possible subword tokens and gradually removes less useful ones. This approach can produce flexible subword segmentation and is particularly useful for multilingual text, where word boundaries and writing systems can vary significantly between languages.
SentencePiece
SentencePiece is slightly different from the other three because it is primarily a tokenization framework, rather than a single tokenization algorithm. It can be used with algorithms such as BPE and Unigram while treating text as a continuous stream rather than requiring traditional whitespace-based word splitting first. This makes it useful for languages where spaces do not consistently separate words, including Chinese, Japanese, and Thai.
How Do These Tokenization Methods Differ?
| Approach | Basic idea
| Common strength
|
|---|
| BPE
| Repeatedly merges frequently occurring sequences
| Efficient and widely adopted
|
| WordPiece | Selects merges based on their contribution to likelihood
| Strong subword representation
|
| Unigram | Starts with many candidates and removes less useful ones
| Flexible probabilistic segmentation
|
| SentencePiece | Framework that can implement BPE or Unigram
| Language-independent tokenization
|
Key Takeaway: There is no single best tokenizer to pick. Each approach makes different design trade-offs around vocabulary size, token efficiency, multilingual support, and model architecture.
How Tokenization Shapes LLM Performance and Context Window Usage
LLM tokenization affects far more API costs. It determines how much text a model can process within its contextual window, how efficiently information is represented, and, in some cases, how well the model handles a particular kind of input.
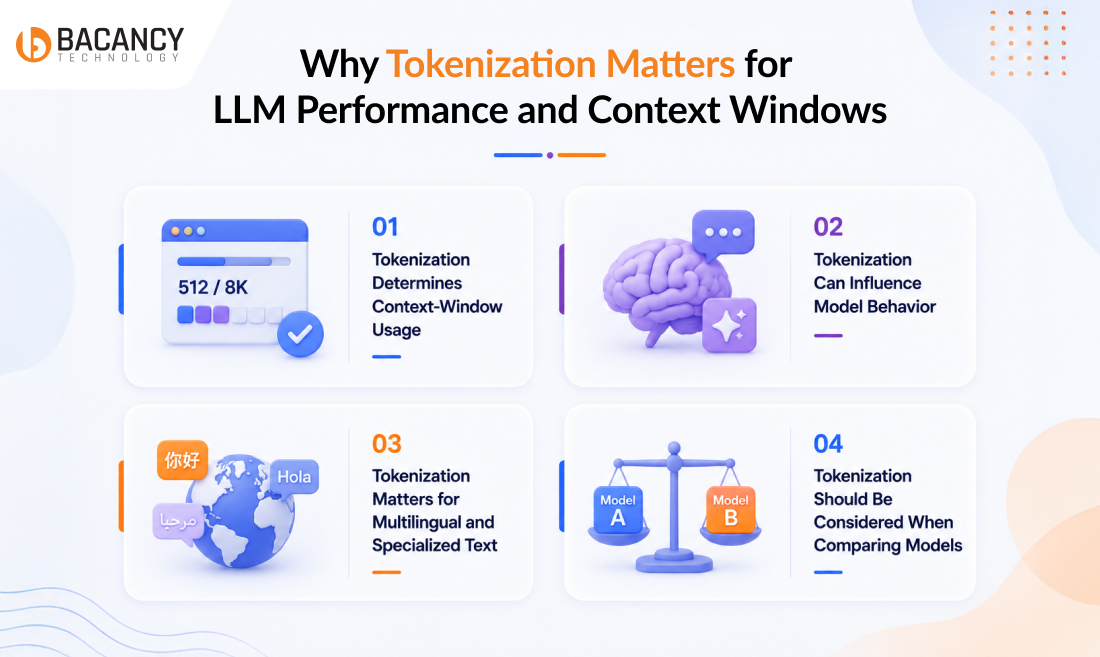
1. Tokenization Determines Context-Window Usage
LLMs’ context window is measured in tokens, so tokenization directly affects how much text can fit into it. A document that contains the same number of words can be used differently based on the available context on how its tokenizer splits the text. This makes token count more useful than character or word count when estimating how much content an LLM can process.
2. Tokenization Can Influence Model Behavior
Token boundaries can also contribute to certain LLM limitations. For example, a word represented as one token does not expose its individual letters as separate input units, which can make letter-counting tasks harder. The numbers can also be divided into different token patterns, contributing to errors in counting or arithmetic.
3. Tokenization Matters for Multilingual and Specialized Text
Token efficiency varies across languages and types of content. Some languages, programming code, mathematical notation, and technical terminology may require more tokens to represent the same amount of information than common English prose. As a result, tokenization in large language models is an important consideration for multilingual and domain-specific applications where context usage and processing efficiency matter.
4. Tokenization Should Be Considered When Comparing Models
The different LLMs can tokenize the same text differently, which can affect token usage, context window requirements, and processing efficiency. When comparing models, teams should therefore consider tokenization besides architecture, benchmark results, and cost.
How Tokenization Drives Your LLM API Costs
The most LLM APIs charge based on tokens, with pricing often separated based on input, output, cached input, and, for some reasoning models, additional token categories. Because tokenization in LLMs determines how much text becomes tokens, the tokenizer can have a direct effect on your total usage cost. The same prompt can consume different numbers of tokens across models, even when the underlying text is identical.
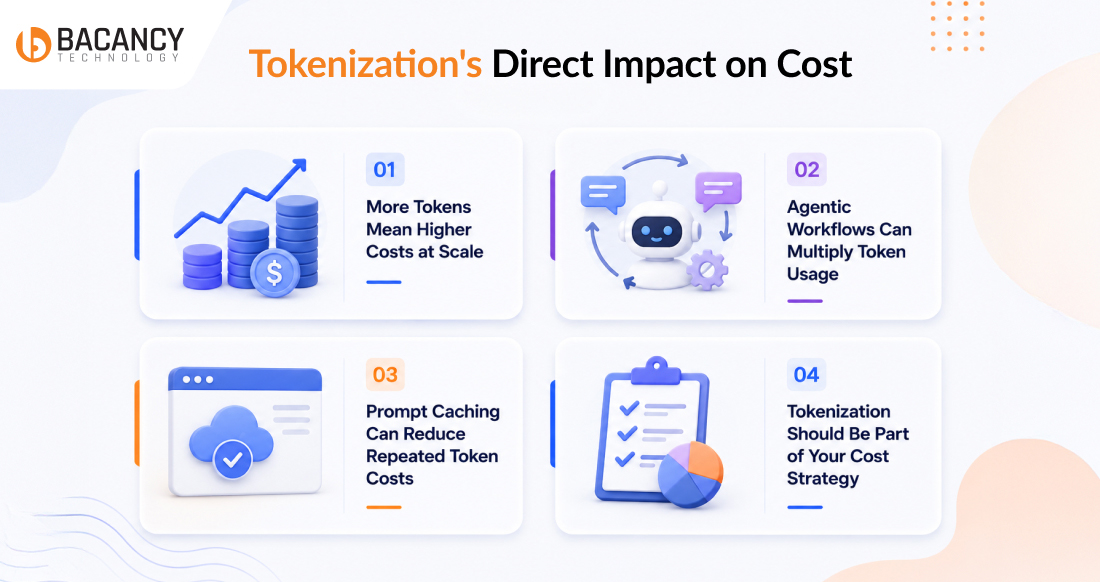
1. More Tokens Mean Higher Costs at Scale
Consider an application sending the same prompt to two models. If one tokenizer produces 1,200 input tokens and another produces 1,600, the second model needs 33% more tokens for the same text. Based on an illustrative rate of $3 per million input tokens, 10 million requests would cost about $36,000 at 1,200 tokens per request versus $48,000 at 1,600 tokens. That’s a $12,000 monthly difference or $144,000 per year without changing the application, prompt, or request volume.
2. Agentic Workflows Can Multiply Token Usage
The cost equation actually becomes more important with agentic workflows. A conventional chatbot may make one model call to answer a user, while an AI agent running agentic workflows can make several calls to plan a task, retrieve information, use tools, verify results, and generate a final response. Each additional call can introduce more input and output tokens, particularly when conversation history or system instructions are repeatedly included. That’s why estimating an agent’s cost based only on the price of a single model response can be misleading. The more useful metric is total tokens consumed per completed task.
3. Prompt Caching Can Reduce Repeated Token Costs
The prompt caching provides another way to control token spend. If the same system instructions, policies, documentation, or other context are sent repeatedly, supported caching mechanisms can reduce the cost of processing that repeated input. For example, sending an 8,000 token system prompt with 100,000 requests per day creates 800 million input tokens of repeated context. At an illustrative fresh-input rate of $3 per million tokens, that represents roughly $2,400 per day, or $72,000 per month, before considering any caching discount.
4. Tokenization Should Be Part of Your Cost Strategy
The real impact of tokenization in large language models becomes visible at production scale. Teams can reduce unnecessary spend by measuring tokens per request, choosing models with efficient tokenization for their workloads, trimming redundant context, controlling agent call volume, and using prompt caching where available.
Why Multilingual Text Costs More Tokens in LLM Applications
LLM tokenization does not treat every language in the same manner. The same idea can require a different number of tokens based on the language and the tokenizer. Those languages that are less represented in a tokenizer’s vocabulary may be split into smaller pieces that can increase token usage and, in turn, API costs. Tokenizers learn from large text datasets, and languages with more representation tend to get more efficient token patterns.
More Tokens Mean Higher Costs
When a multilingual application processes millions of requests, even a small difference in token usage can become expensive. For example, if the same workload uses 25% more tokens in another language, its token-related cost can also be roughly 25% higher at the same pricing rate.
Measure Cost by Language
AI applications that work globally, using one average token estimate, can hide important differences. Teams should test real prompts in each target language and track tokens per request and cost per task. This gives a more accurate picture of production costs.
Optimize for Your Target Languages
The goal is not to avoid multilingual applications, but to choose models and tokenizers that handle your target languages efficiently. You need to compare the token usage across models, reduce unnecessary context, and use caching where available to help control costs.
How Different LLMs Tokenize Text: GPT, Claude, Llama, and Gemini
LLM tokenization doesn’t follow standardization across providers. GPT, Claude, Gemini, and Llama use different tokenizers, vocabularies, and tokenization methods, so the prompt can produce different token counts on each model. That difference matters most as it affects context window usage, processing efficiency, and, in many cases, the cost of running an application.
| Model family
| Tokenization approach
| Key consideration
|
|---|
| GPT (OpenAI)
| BPE-based tokenizer
| Efficient representation varies by model and encoding
|
| Claude (Anthropic)
| Proprietary tokenizer
| Token counts can differ between model generations
|
| Gemini (Google)
| Google tokenizer
| Token counts are measured through Google's model-specific tools
|
| Llama (Meta)
| BPE-based tokenizer
| Token efficiency varies across Llama generations
|
The important point is that 1,000 characters or 1,000 words do not necessarily equal the same number of tokens across models. A prompt that uses fewer tokens with one provider may use more with another, even though the text and task remain identical.
Tokenizers Can Change With New Models
Tokenizers can change when providers release new model generations. This means the same text may use a different number of tokens after a model upgrade, especially with code, technical content, or multilingual text.
Count Tokens Before Comparing Models
When comparing LLM providers, don’t assume the same text will use the same number of tokens. Test your actual prompts with each provider’s tokenizer or token-counting tool. This gives you a more accurate estimate of token usage, context limits, and cost.
Common Tokenization Pitfalls: Numbers, Code, and Rare Words
Some types of input are harder to tokenize efficiently than ordinary text, such as numbers, source code, and rare or technical words, which can produce unexpected token counts and affect how an LLM handles the input.
Numbers
A number such as 48291 may be represented as one token or several smaller tokens, depending on the tokenizer. This can make precise counting and arithmetic harder, so high-accuracy applications should use verification tools.
Code
There is code that contains symbols, brackets, indentation, and long identifiers that can consume tokens quickly. Large code-heavy prompts, common in workloads such as LLM-based code migration, can therefore use more context than their character count suggests.
Rare and Technical Words
As uncommon words, technical terms, and unfamiliar names may be split into multiple subword tokens. This can increase token usage and make specialized content less efficient to process.
Note: What looks like one word, number, or line of code from a human perspective may be several tokens to an LLM. Once you understand that tokenization pattern, you can control cost, context usage, and reliability.
How to Cut Token Usage in Production LLM Applications
Optimizing tokenization in large language models is not about one trick. The biggest savings usually come from reducing unnecessary context, choosing the right model, and measuring real token usage.
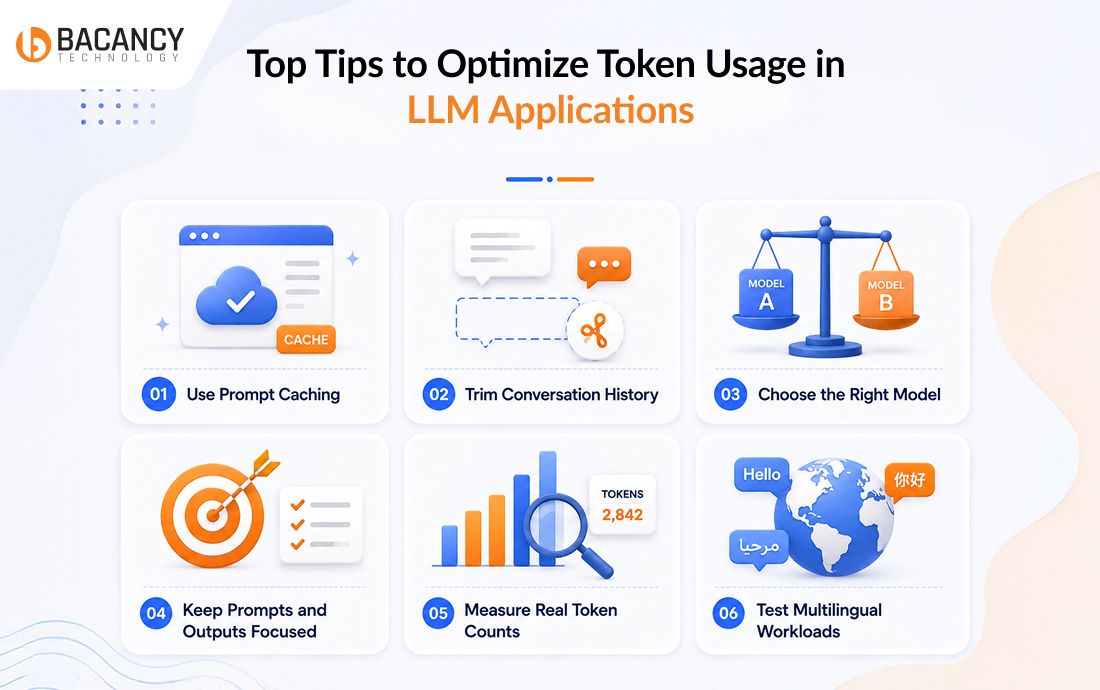
1. Use Prompt Caching
If you employ prompt caching, it helps to prevent repeated content and the same context, such as system instructions, tool definitions, and reference material.
2. Trim Conversation History
You can avoid sending the entire conversation or document when only part of it is relevant. Try summarizing older messages and retrieve only the information needed for the current task, which puts real weight on the vector database behind your RAG layer.
3. Choose the Right Model
Try using smaller models for simple, high-volume tasks and reserve more capable models for complex reasoning. Matching the model to the task is one of the fastest ways to reduce overall token costs, so weigh token efficiency alongside the other factors that decide how to choose the right LLM model.
4. Keep Prompts and Outputs Focused
You can eliminate repeated instructions, unnecessary examples, and irrelevant details. Set appropriate output limits so the model does not generate more text than your application needs.
5. Measure Real Token, Counts
Don’t rely on word-count estimates when planning production costs. Use the provider’s tokenizer or token-counting tool to measure real usage, especially after changing models or prompts.
6. Test Multilingual Workloads
You can enable token efficiency that varies across languages, code, and specialized text. Take representative inputs from your actual workload to understand how many tokens your application really uses.
Bacancy Technology Case Study: Token-Efficient LLM Architecture in Healthcare
Our US hospital client was using an LLM-powered clinical documentation assistant across multiple sites. As usage grew, every request continued sending the network’s complete clinical guidelines and formatting instructions, even though most of this context rarely changed. This repeated context was driving up LLM costs without improving the actual note-generation task.
Our expert LLM engineers first analyzed token consumption and found that the static guidelines were the largest recurring contributor. The team moved frequently reused instructions into a cached prefix and replaced full guideline documents with specialty-specific context retrieved for each task. A lightweight redaction layer also removed patient identifiers before they reached the tokenizer, protecting PHI earlier in the pipeline.
These changes allowed our US hospital client to optimize its live workflow without compromising clinical accuracy, delivering 68% lower monthly LLM spend and 41% faster note-drafting turnaround, while reducing repeated context and keeping PHI out of the model’s token stream.
How Bacancy Technology Helps You Build Token-Efficient LLM Systems
Bacancy Technology helps businesses design and optimize LLM models with token efficiency in mind. Our team of expert AI engineers helps select suitable models, structure prompts and context for efficient token usage, implement caching strategies, and monitor token consumption as applications scale.
- We consider tokenization right an architecture decision, not just a prompt optimization task; it affects model selection, caching, context design, multilingual support, and long-term LLM costs.
- We benchmark models against your real workloads to identify the most token-efficient option for your content and use case.
- Our experts structure prompts so stable instructions and tool definitions can be cached and reused, reducing repeated token costs.
- We measure token usage across languages and improve efficiency through domain-specific LLM fine-tuning services.
- We retrieve, rank, and trim context so your model processes only the information needed for accurate responses.
- We track token consumption and flag unexpected increases after model, tokenizer, or prompt changes.
- We build and scale production-ready systems with token efficiency considered throughout the architecture.
Whether you’re building a multilingual AI product, looking for large language model development, or optimizing an existing LLM application, the right tokenization strategy can improve both cost efficiency and performance. If your business requires hands-on expertise to get this right, contact Bacancy Technology to design, optimize, and scale a token-efficient LLM system from the base up.
Frequently Asked Questions (FAQs)
There is no fixed number. As a rule of thumb, one English word is close to 1.3 tokens on most modern tokenizers, but that ratio shifts a lot with technical terms, code, numbers, and especially with non-English texts.
Agentic AI workflows often make multiple model calls for planning, retrieving information, using tools, verifying results, and generating responses. As each step may resend context or instructions, LLM tokenization can result in significantly higher token usage per task than a single chatbot response.
Prompt caching primarily reduces the cost of repeated input tokens. It does not change the prompt or model response, but makes it an effective way to optimize tokenization in LLMs while maintaining the same output quality.
Generally, codes contain symbols, brackets, indentation, and identifiers, which often break into multiple tokens. As a result, tokenization in large language models can be less efficient for code than for plain English, increasing token usage and context consumption.
No. The tokenizer is tied to the model and its training, so you generally cannot replace it without changing the model. With tokenization in large language models, your main options are to optimize the input, use caching, or choose a model with a more efficient tokenizer for your workload.