Quick Summary
Through this blog, you will learn how 10 data security strategies can address common AI privacy concerns, from data classification and minimization to permission-aware RAG, vendor controls, retention, and AI monitoring. You’ll also get a practical 30/60/90-day roadmap to strengthen AI data security and build safer, more compliant AI systems. Through this blog, you will learn how 10 data security strategies can address common AI privacy concerns, from data classification and minimization to permission-aware RAG, vendor controls, retention, and AI monitoring. You’ll also get a practical 30/60/90-day roadmap to strengthen AI data security and build safer, more compliant AI systems.
Table of Contents
Introduction
Most organizations approach AI privacy concerns from the wrong direction. They spend months evaluating models, comparing vendors, testing prompts, and asking which AI system is safest. But the real exposure often sits one layer below the model, in data nobody classified, minimized, or checked for who can access it.
According to IBM’s cost of data breach report, 97% of organizations are facing AI security incidents because of poor access controls, and 63% lack adequate AI governance policies. That distinction matters most because it changes how organizations should think about AI privacy and where they should spend their security budgets.
AI creates new pathways for data to move. A customer record can flow into a prompt, confidential documents can become embedded, and production data can end up in a training set. The fundamental controls remain familiar through classifying data, minimizing what AI can access, preserving permissions, controlling where information goes, and monitoring what comes back. Ideally, AI privacy challenges are often more of a security problem than a model problem.
AI Privacy Risks and Data Security Strategies at a Glance
Each row shows the AI privacy risk, the data security strategies that address it, the sign that tells you the control is missing, and the consequence of leaving the gap unresolved.
| AI Privacy Concern | Data Security Strategy | How You Know You Have It | What It Costs You |
|---|
| Data reaches models that should never have seen it | Classification and AI eligibility tagging | Nobody can name which datasets are approved for AI use | Penalties for processing data you had no basis to use |
| Prompts carry more personal data than the task needs | Data minimization at the pipeline layer | Whole customer records get passed in as context | Every prompt log turns into a breach liability |
| Personal data sits inside training sets | De-identification and synthetic data | Training data was copied straight out of production | The model repeats real customer details back to users |
| Search returns files the user can't open anywhere else | Permission-aware RAG | Your vector store has no access rules attached to it | Staff reading salary, legal, or patient records |
| A vendor's model processes your data unprotected | Encryption in transit, at rest, and in use | Encryption stops at the API boundary | Failed SOC 2 audits and enterprise deals stalling |
| Your data trains someone else's model | Zero-retention and no-train clauses | Nobody has read the vendor's default terms | Your proprietary data is inside a competitor's answers |
| Personal data is left in a model's answer | Input and output guardrails | Nothing inspects what the model sends back out | Disclosure of one customer's data to another |
| Staff paste confidential files into unapproved tools | Shadow AI discovery and tool register | You have no list of the AI tools currently in use | Data loss you will never be able to trace |
| You can't delete data a customer asked you to erase | Retention schedules and deletion paths | Nobody has tested a deletion request end-to-end | Erasure requests that you are legally unable to fulfil |
| No record of what the system used or why | Inference logging and data lineage | You can't reconstruct why the model answered as it did | No defence when a regulator challenges a decision |
10 AI Data Security Strategies That Solve AI Privacy Concerns
AI privacy risks are rarely just model problems; they often start with how data is collected, classified, accessed, shared, and retained. These 10 strategies focus on securing data across the AI pipeline, from source systems and training datasets to retrieval, prompts, and outputs.
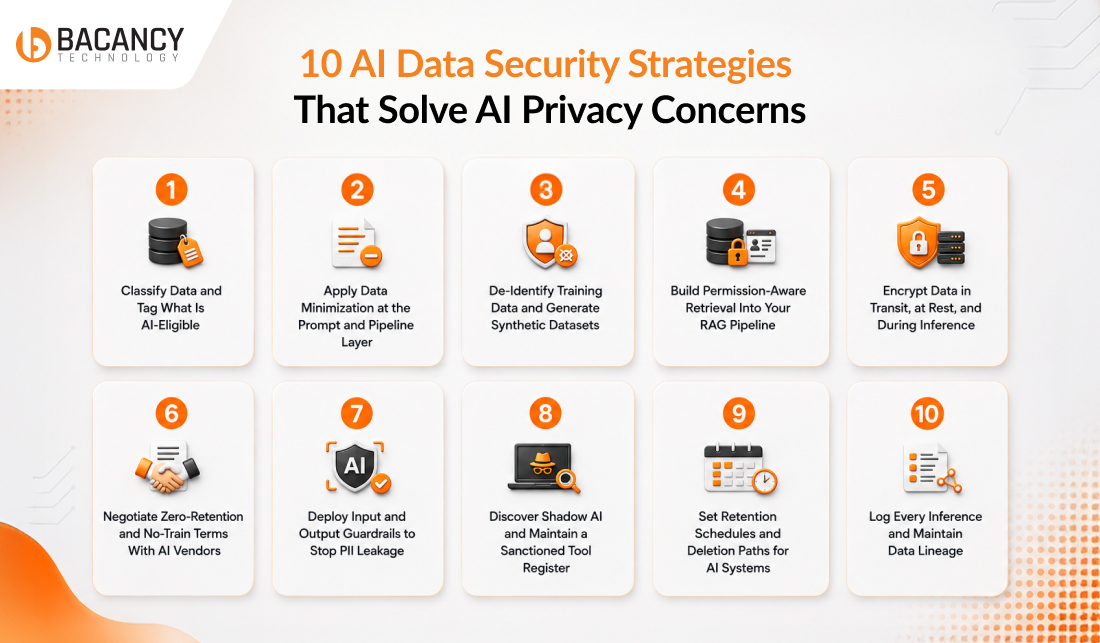
1. Classify Data and Tag What Is AI-Eligible
The Concern
When sensitive records reach AI systems because nobody has explicitly decided which data is allowed for AI use or which is not. Most organizations already follow data classification in terms of public, internal, confidential, and restricted. But that scheme answers only one question: how sensitive the data is.
It does not answer whether that data can be embedded, retrieved, cached, used for evaluation, or included in a training or fine-tuning dataset. Those are separate decisions, often subject to different purposes, permissions, and legal requirements.
The Solution
To achieve the solution, it needs to make AI eligibility separate from the data attribute, keeping the existing sensitivity classification. Also add an AI use tag at the source with clear values such as prohibited, retrieval only, training allowed, or synthetic only.
2. Apply Data Minimization at the Prompt and Pipeline Layer
The Concern
AI context possesses far more personal or sensitive data than the task actually needs. It often begins with a shortcut that doesn’t seem threatening. A developer needs an AI assistant to summarize the customer’s last three support tickets. The fastest implementation serialized the entire customer record and sent it to the model.
The task may require the ticket text and account tier, where the prompt now contains the customer’s date of birth, billing address, payment information, internal risk flags, and other fields that have nothing to do with the task. Even one unnecessary query can create multiple new copies of personal data, each with its own retention period and access controls, with exposure risk.
The Solution
The control is straightforward, where you need to use field-level allow lists during context assembly and scope retrieval of the information the task actually needs. Instead of passing an entire customer object, define the specific fields the model is permitted to receive.
3. De-Identify Training Data and Generate Synthetic Datasets
The Concern
The personal data generally resides in the training and fine-tuning sets, where models may memorize and reproduce it later. The research demonstrates that LLM models can reproduce examples from their training data, with the risk of becoming more significant where sensitive or unique records appear repeatedly. That is exactly the kind of exposure created when teams copy production CRM exports, customer records, or other personal data directly into training pipelines.
The problem is not limited to what the model eventually memorizes. Here, raw copies also remain in object storage, development environments, evaluation datasets, and other parts of the training workflow.
The Solution
The solution is to de-identify data before it enters the training environment using techniques such as tokenization, masking, or format-preserving encryption. The different privacy measures can add another layer of protection when the goal is to learn population-level patterns rather than individual records. For testing, evaluation, and development, synthetic data from tools such as Gretel, MOSTLY AI, or the open-source SDV can often replace real records entirely.
Secure Your AI Pipeline with Enterprise-Grade Data Governance
Get AI strategy consulting from Bacancy Technology to close security gaps, enforce permission-aware RAG, and build compliant, enterprise-ready AI systems.
4. Build Permission-Aware Retrieval Into Your RAG Pipeline
The Concern
The retrieval layer returns documents that users have no right to access anywhere else. When a company connects internal documents with FAG system, those documents are processed into chunks and stored as searchable embeddings. The problem lies in the fact that original file permissions do not automatically become part of that new search layer. Companies need to have strict access controls in SharePoint, but if those permissions are not carried into the RAG pipeline, the AI assistant can retrieve information that the user could never access directly.
The Solution
It needs permission-aware retrieval where each document carries its original access rules and those rules are checked against the identity of the person making the request before anything is returned. Tools such as Azure AI Search support security trimming, while vector databases such as Pinecone, Qdrant, and Weaviate can apply metadata filters to restrict retrieval. The permissions also need to stay current; if an employee changes roles or loses access to a document in SharePoint, that change must reach the RAG index quickly.
5. Encrypt Data in Transit, at Rest, and During Inference
The Concern
Sensitive data can be exposed while an AI model is processing it, even when the same data is encrypted during storage and transmission. Most organizations already encrypt data at rest and in transit. And the overlooked gap is data in use. During inference, prompts, retrieved documents, and other sensitive context must be available to the model in memory. The encryption of the database or network connection does not protect that processing stage. This becomes particularly important when sensitive information is sent to a third-party model provider, where organizations need to understand exactly how and where that data is processed.
The Solution
The solution is to extend encryption controls across all three states. Use TLS for data in transit, strong encryption and customer-managed keys for stored data, and private connectivity such as Azure Private Link or AWS PrivateLink where appropriate. For highly sensitive workloads, confidential computing technologies such as AMD SEV-SNP, Intel TDX, and NVIDIA confidential computing can provide protection while data is being processed.
6. Negotiate Zero-Retention and No-Train Terms With AI Vendors
The Concern
Your data can be retained or used to improve a vendor’s models even when there is no security breach. By sending data to an external AI provider, it creates a new data-processing relationship. The provider may process prompts and outputs for abuse monitoring, troubleshooting, service improvement, or model training depending on the product and contract.
The Solution
It requires the use of data use restrictions following contractual needs before production data reaches the provider. It takes explicit zero-retention and no-training terms where appropriate, understands subprocessors and data locations, and ensures the relevant Data Processing Agreement covers the AI service. Avoid assuming that a vendor’s general enterprise privacy statement applies to every model or endpoint.
The Concern
Personal or confidential information can enter the model unnecessarily or appear in its response even when the user should never receive it. Most teams focus heavily on what goes into the model by detecting sensitive information in prompts, blocking certain requests, and filtering retrieved content. But the more visible privacy failure often happens on the way out. A model can reproduce sensitive information from its context, return another customer’s details, or expose confidential content retrieved from a connected data source.
The Solution
The solution is to place PII and sensitive-data controls on both sides of the model. Conduct scanning before they reach the model, redact or tokenize information that is not required, and inspect outputs before they reach the user or downstream system. You need to define policies for what types of personal, financial, health, or confidential information can appear in responses and block or redact violations automatically.
8. Discover Shadow AI and Maintain a Sanctioned Tool Register
The Concern
Employees can move confidential information into AI tools that security and compliance teams do not know exist. Shadow AI begins without proper intentions; it starts innocently. An employee finds a public AI tool that summarizes documents better, writes code faster, or analyzes a spreadsheet more conveniently than an approved application. The problem begins when they paste customer records, source code, contracts, or internal documents into it without understanding where that data goes or how long the provider keeps it. By the time security teams discover the tool, sensitive information may already have left the organization’s controlled environment.
The Solution
The solution needs to find what employees are actually using before deciding what to block. You need to use network, browser, endpoint, identity, and SaaS discovery signals to build an inventory of AI services in use, then classify them as approved, restricted, or prohibited. Maintain a sanctioned AI tool register that records the approved use case, data types permitted, vendor, retention terms, and owner.
9. Set Retention Schedules and Deletion Paths for AI Systems
The Concern
Organizations collect AI-related data they cannot reliably find, control, or delete when the retention period ends or a customer requests erasure. AI systems can create more copies of data than traditional applications, such as prompts, responses, conversation histories, embeddings, caches, evaluation datasets, monitoring logs, and sometimes training or fine-tuning data. If each layer has a different owner and retention period, an organization may be able to delete the original customer record while leaving copies of the same information inside an AI workflow. That creates both a privacy risk and a compliance problem.
The Solution
The solution requires designing retention and deletion before the AI system goes into production. You need to define how long prompts and outputs are retained, automatically expire unnecessary logs and caches, establish deletion procedures for embeddings and vector indexes, and document what happens when data is used in training or fine-tuning. Then test the entire process end-to-end: start with a real data-deletion request and verify that every downstream copy can be identified and handled. If you cannot demonstrate how AI-related data gets deleted, you do not yet have a complete retention control.
10. Log Every Inference and Maintain Data Lineage
The Concern
When an AI system produces a sensitive or disputed response, you may have no way to determine what data it used, which controls were applied, or why that information was returned. AI responses are rarely generated from a single source. A response can depend on the user’s identity, system instructions, retrieved documents, model version, prompt context, and multiple data sources. If those events are not recorded, an organization cannot reliably reconstruct what happened after an incident or demonstrate to a regulator that the system handled data appropriately.
The Solution
To maintain inference-level logging and end-to-end data lineage, record the relevant user or service identity, model and version, timestamp, policy decisions, and other metadata needed to reconstruct the interaction while avoiding unnecessary storage of sensitive prompt or response content.
Build Secure AI Systems With the Right Expertise
Hire AI developers from Bacancy Technology to turn your AI roadmap into secure, production-ready systems, from RAG and LLM integration to AI security and maintenance.
Where Most AI Data Protection Programs Go Wrong (Three Failure Patterns)
The ordering matters more than ambition. You cannot control what you cannot see, and you cannot prove a control works without any evidence. A practical 30/60/90-day sequence is to establish visibility first, put controls around the highest-risk data flows second, and build evidence that those controls work third.
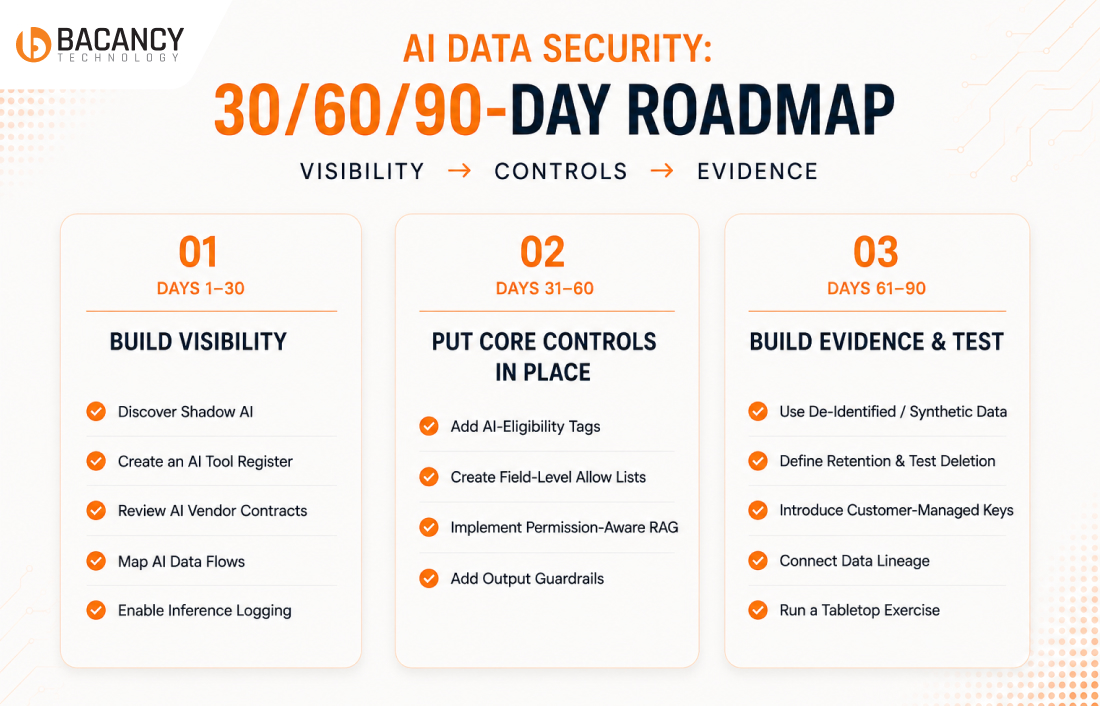
Days 1-30: Build visibility
At first, discover shadow AI through egress logs, browser activity, and OAuth grants. You have to create the first version of your sanctioned AI-tool register. You need to review every AI vendor contract for retention, training, and data-use terms. Map the data flows already feeding your AI systems, and turn on inference logging even if the first version is basic. You can improve a log once it exists; you cannot recover events that were never recorded.
Days 31-60: Put the core controls in place
Then apply AI-eligibility tags to your five highest-risk data domains and add field-level allow lists to your three busiest AI pipelines so models receive only the data they need. Then implement permission-aware retrieval for the RAG system containing your most sensitive documents. Add output guardrails to customer-facing AI systems to detect and block sensitive information before it reaches users.
Days 61-90: Build evidence and test the controls
Move training and evaluation workflows to de-identified or synthetic data wherever possible. Then define retention schedules for every AI-related data store and test one deletion request from source to final copy. Try introducing customer-managed keys where appropriate and connecting data lineage from embeddings back to their source records, and finish with a tabletop exercise based on a realistic failure, such as an AI assistant returning one customer’s confidential contract terms to another.
How Bacancy Technology Turns AI Data Security Strategies Into an Actual Roadmap
Bacancy Technology’s AI consulting engagement begins with that data-flow assessment tracing information from source systems into prompts, vector databases, training pipelines, model providers, and outputs. The goal is to find the gaps that create real exposure from unclassified data entering AI workflows, entire records being passed when only a few fields are needed, or retrieval systems exposing documents without enforcing the source system’s permissions.
From there, the roadmap is built around the highest-risk gaps rather than another generic checklist. The classification and AI-eligibility controls come first, followed by data minimization, permission-aware retrieval, encryption, vendor controls, guardrails, retention, and lineage. Through AI development services, these controls can be built directly into the applications and pipelines that move the data, so security decisions are enforced automatically rather than left to individual developers or employees.
Conclusion
Those businesses that manage AI privacy problems well are not the ones with the strictest AI policies. They are the ones who know what data AI can access, who can access it, where it goes, and how it can be deleted. That is the foundation of effective data security.
As AI adoption grows and regulations continue to evolve, leaving these gaps unresolved will only become more costly. Whether you are strengthening your internal team or looking for data engineering services with experience in secure AI and permission-aware RAG, the goal is to build data security strategies into the AI system from the start. So begin by finding where AI is already being used, identify the data flowing into it, assign an owner, and fix the highest-risk gap first.
Frequently Asked Questions (FAQs)
The biggest concerns include sensitive data entering AI systems unnecessarily, unauthorized retrieval of confidential documents, personal data appearing in model outputs, vendor retention or training on customer data, shadow AI, and the inability to trace or delete data across AI workflows.
In many enterprise use cases, it is primarily a data governance and security problem. The model selection matters, but controls such as data classification, minimization, access management, retention, encryption, and monitoring determine what information reaches the model and who can receive it.
We use retrieval when the model needs access to changing customer or business information. It keeps the information outside the model’s weights, making it easier to update, restrict, and remove, considering only when there is a clear reason that retrieval cannot meet the requirement.
Try to enforce authorization before the retrieved content reaches the model and carry the source document’s permissions into the retrieval index, check them against the requesting user’s identity at query time, and keep those permissions synchronized with the source system.
It can be difficult to guarantee complete removal once personal data has been incorporated into model weights. The training data may be memorized, and the original access controls cannot simply be applied to information encoded in the model. The safer approach is to minimize and de-identify data before training, use synthetic data where possible, and avoid fine-tuning when controlled retrieval can solve the use case.